• Les luttes sociales en livre audio | Caracole
    https://caracole.audio/qui-sommes-nous

    Le projet
    Caracole édite, produit et diffuse des livres audio à caractère politique. Cette plateforme est un carrefour à la croisée des luttes, qui vise à mettre à disposition des ressources dans une démarche d’éducation populaire.
    Tous les titres de notre catalogue sont des adaptations d’ouvrages déjà parus en version papier.

    La narration
    Nos livres audio sont interprétés par des conteur·ses qui se sentent concerné·es par les luttes, et qui sont soit des comédien·nes, soit les auteur·ices en personne, soit des personnalités de la gauche critique.
    La voix est un puissant moyen d’entrer dans un texte. Avec ce projet, il s’agit d’offrir une nouvelle manière – immersive, incarnée et inclusive – d’accéder à des contenus qui nous paraissent fondamentaux pour équiper les luttes, affûter les esprits et comprendre les grands sujets de notre époque.

    Mon abonnement
    Plutôt qu’une boutique dans laquelle chaque individu viendrait acquérir des titres au gré de ses moyens, Caracole a été conçu·e comme une bibliothèque. L’achat d’un abonnement vous donnera accès à l’intégralité du catalogue.
    Nous misons sur un tarif abordable pour faciliter l’accès aux contenus.

    https://www.youtube.com/watch?v=Xxso1Pln2Y4

    #livres #audio #livres_audio #bibliothèque #luttes

  • What Was the Internet ?
    https://www.bostonreview.net/articles/what-was-the-internet

    L’état des choses dans l’internet vu par quelques personnes assez intelligentes et sincères.

    6.8.2026 by Siva Vaidhyanathan, Avery Dame-Griff, Joanna Walsh, Chad Wellmon, Cory Doctorow, Matt Lord - As AI overtakes the web, five writers reflect on how far it’s fallen and what comes next.

    Joanna Walsh’s latest book is Amateurs! How We Built Internet Culture and Why it Matters.

    For as long as it’s been around, we haven’t been sure how to feel about it. The utopians had their favored metaphors: cyberspace; a global village; the electronic frontier, digital commons, or new public sphere. If American literature, as Emerson said, is “in the optative mood,” the same has been true—maybe truer—of so much thinking about the internet.

    But it didn’t take long for disillusionment to set in. A few years after British computer scientist Tim Berners-Lee invented the World Wide Web at CERN in 1989, critics began to sound the alarm on the “Californian Ideology”: the insidious creep of corporate greed in the guise of bohemianism. Since then, the story of the web’s decline has paralleled that of Silicon Valley and the “new economy” of neoliberal globalization it stood for. Social media, once a vehicle of “participatory culture” and “networked protest,” has been enshittified. Big Tech has gone red (in the GOP, not communist, sense). Attention merchants lock us into doomscrolling while platform capitalism, the backbone of today’s national security state, extracts, surveils, and kills. Despite valiant efforts by activists and reformers, it’s been the dystopians’ world—or at least the realists’—for some time now: an age of techno-feudalism, digital colonialism, the new Jim Code.

    With the rise of AI, however, some new mood seems discernible, at least around the edges: the elegiac. A lot of the web is being swept away. In May, Google overhauled its iconic search box for the first time since 2001, signaling its all-in on the “intelligence age.” As chatbots hallucinate and hide their sources, search results become harder to browse, and digital life becomes ever more atomized, online access to information looks more imperiled than ever. Wikipedia has managed to survive—a miraculous exception that proves the rule—but it’s staring down new threats. Boston Review has been online since 1995, but our search engine traffic is falling, like everyone else’s. If work is published on the net and no one can navigate to it, does it leave a trace?

    In other words, is this the end of the web itself? And if so, is some kind of eulogy in order?

    “Just as I’d hoped, [the web] has enabled a flourishing of human creativity and self-expression,” Berners-Lee writes in his recent memoir, This Is for Everyone. But “to ensure the web agents serve people—not corporate profits, not governments, not themselves, but people—it’s critical that we develop systems today that put the human first.” We asked five humans who’ve been paying attention what to make of this moment. Read on for their reflections: about how the web used to work and what it used to feel like, the strange and sorry thing it’s become, and the good that’s worth remembering when so much of what we love is dying, or already long gone.

    —Matt Lord

    “Infrastructural Imperialism”
    by Siva Vaidhyanathan

    “The Scale’s the Thing”
    by Avery Dame-Griff

    “Net Positives”
    by Joanna Walsh

    “That Obscure Object, Desire”
    by Chad Wellmon

    “Managed Decline”
    by Cory Doctorow
    Inside a Google data center in Dalles, Oregon, October 2012. Image: Connie Zhou/Google/ZUMAPRESS.com
    Infrastructural Imperialism

    Siva Vaidhyanathan

    In October 2009, Google cofounder Sergey Brin took to the op-ed page of the New York Times to defend a project that had, by then, attracted lawsuits from the Authors Guild and the Association of American Publishers and more than a little suspicion from librarians and scholars of the web. The subject was Google’s bold, global plan to “digitize all books.”

    No one had asked the company to launch Google Books; it seemed not to be doing it for any immediate boost in revenue. Instead, Brin claimed, they were looking out for the good of humanity. “The vast majority of books ever written are not accessible to anyone except the most tenacious researchers at premier academic libraries,” he wrote. He referred to a flood that had damaged the Stanford library stacks in 1998—the very libraries he and cofounder Larry Page had once accessed as graduate students—as proof of print’s fragility and the moral urgency of digitization.

    All those centuries of books, in hundreds of languages: it was never about the good of humanity. It was about laying the groundwork for generative AI.

    It was a lovely piece of writing in its way, and I don’t doubt that Brin believed every word of it. This was digital philanthropy offered up in the now-classic register of Silicon Valley benevolence: a hot, young company, incensed by the slowness and oldness of something, stepping in to do what creaky institutions couldn’t or wouldn’t do themselves, and asking for gratitude rather than payment. But Brin didn’t reveal what all that scanned, machine-readable, multilingual text was really for. Now we know: his company was compiling the largest collection of digestible text in human history in order to build and train a large language model. All those centuries of books, in hundreds of languages, drawn from dusty library stacks: it was never about the good of humanity. It was about laying the groundwork for generative AI—and that was the plan all along.

    That technology is now ruining the World Wide Web, the collection of documents, images, and video that we so unwisely entrusted Google to manage for us. Whether one calls this a bait-and-switch or simply the foreseeable convergence of a data-maximalist research culture with an unprecedented act of data acquisition, the effect is the same: the project that Brin sold to the public as an act of preservation turned out to be infrastructure for a radical act of enclosure—creating the very system now replacing the search engine and the open web itself.

    In those years I wrote a book, The Googlization of Everything, warning that Google had become something the world had never seen before: a private company entrusted, almost by accident and almost entirely without public deliberation, with the organization of the totality of human knowledge. I called this condition “Googlization,” and I broke it into three overlapping projects. First, Google was Googlizing us, shaping our habits of attention and self-disclosure through the surveillance of search. Second, it was Googlizing the world: mapping streets, scanning books, and laying fiber with the swagger of a nineteenth-century railroad baron. And third, it was Googlizing knowledge itself—inserting a ranking algorithm between every citizen and the record of human thought, and doing so with a design so elegant and an interface so spare that few people thought twice.

    Revisiting that argument now, I realize something has changed that I didn’t fully anticipate: Google has stopped pointing. For its entire history, whatever its crimes and sins, Google Search performed one basic benevolent function: it sent our attention from Google to some source that most likely helped resolve a question or indulge an interest. You typed a query, and the company’s ranking algorithm—proprietary, opaque, contestable, but ultimately effective and useful—served up a list of doors onto the wider web. You clicked, and you left Google’s house to visit someone else’s. That mere act of departure, unglamorous as it sounds, was the thread connecting search to the older ideal of the public sphere. It was the residue of an Enlightenment premise: that citizens benefit from encountering a plurality of sources, weighing them, and forming judgments amid the friction of disagreement. Or, at least, Google wanted us to believe that. Many of us did.

    Google has now severed that thread. Type a query into Google today and more often than not you are met with a pile of slop: a synthesized paragraph, stitched together by an LLM, that purports to answer your question so directly and bluntly that you have little reason to go anywhere else. Google calls these paragraphs “AI Overviews.” A more expansive version, “AI Mode,” dispenses with the pretense of links altogether and simply converses with you. By 2025, AI Mode had reportedly surpassed a billion monthly users, with Google boasting that query volume was doubling every few months. The infrastructural imperialism I described in 2011—the steady, unaccountable extension of one company’s dominion over the mechanisms by which we find things out—has entered its final and most totalizing phase. Having organized the web, Google now proposes to replace it.

    It’s worth being precise about what has changed. The shift from ranking to rendering is not a matter of degree; it’s a matter of kind. A ranked list of links, however manipulated by SEO and however biased by commercial incentive, still preserved the plurality of the web as a formal feature of the experience. You at least saw ten different domains, ten different voices, ten different institutional pedigrees; the very act of scanning them—this one a newspaper, that one a blog, this one a government site, that one a forum thread—was a small, constant education in source criticism. The ranking was Google’s judgment, yes, but the sources remained legible as sources. An AI Overview suppresses all that. It takes the labor of dozens of writers, editors, researchers, and institutions, blends it into a single fluent voice with no discernible author, and presents it as if it had emerged from nowhere in particular. Links are demoted to a small cluster of citation chips, easy to ignore, appended as a footnote or afterthought.

    It used to be that when you clicked, you left Google’s house to visit someone else’s. That mere act of departure was the residue of an Enlightenment premise.

    In other words, AI Overview offers the seductive promise that the messy, effortful, contestable business of finding things out—comparing sources, noticing bias, tolerating ambiguity, occasionally being wrong and having to revise your view—can be replaced by a single, confident, algorithmically fluent paragraph. It substitutes the appearance of consensus for the reality of disagreement, laundering the gamut of human knowledge into a single, bland, authoritative-sounding voice with a penchant for hallucination. We have traded a system that was biased and commercially distorted for one that is biased, commercially distorted, and prone to simply making things up, all while sounding more confident than any of the sources it cannibalized to produce its answer.

    Recent field research illustrates what’s at stake. A Pew study found that when an AI Overview appears, only about 8 percent of users go on to click a traditional search result, compared with 15 percent when no overview is present, and a mere 1 percent of users click through on the links embedded in the overview itself. An Ahrefs analysis published early this year found that AI Overviews correlate with a 58 percent reduction in click-through rates on top-ranking pages—nearly double the decline measured less than a year earlier, suggesting the effect is not a one-time adjustment but an accelerating trend. Seer Interactive, an industry analytics firm, clocked a 61 percent year-over-year decline in organic click-through for queries that trigger an overview. And in Google’s own AI Mode, the zero-click rate—the share of searches that end without the user visiting any external site at all—has been measured as high as 93 percent. Across the whole of Google Search, industry trackers now place the zero-click share at roughly 60 to 68 percent of all queries.

    These are not marginal effects, and they reflect a bid for control that goes beyond Google Books. Unlike a library’s back catalog, the web depends on continuous revenue and continuous attention to survive. A book, once digitized, sits inertly on a server; a newspaper, a recipe site, a small nonprofit’s explainer page, or a local news outlet needs the next visitor, and the one after that, in order to keep publishing at all. Google’s summarization apparatus consumes the work of the open web in order to render the open web unnecessary to visit.

    Of course, Google’s overviews and AI Mode are trained on, and generated in real time from, the work of publishers, journalists, encyclopedists, bloggers, forum contributors, recipe writers, and millions of other ordinary web authors—the same open web that Google’s original ranking algorithm was built to organize. Classic search occasionally (if unfairly and unevenly) rewarded source publishers with traffic: that reciprocal arrangement was the thing that made the commercial web possible for two decades. The generative layer breaks that circuit. Google now ingests the open web’s output to manufacture an answer that keeps the user inside Google’s own interface, denying the originating site the visit—and the ad impression, and the subscription prompt, and the newsletter signup—that used to be the whole point of writing something worth ranking.

    Publishers have not taken this quietly; among other things, they’ve launched a bevy of lawsuits. In apparent recognition of the problem, Google has rolled out cosmetic fixes—a “Further Exploration” module tacked onto the bottom of an overview, offering a few curated links after the user’s question has already been answered above the fold. What should worry us here is not merely that individual publishers are losing revenue, painful as that is. It’s that the ecosystem of incentives which made the open web worth writing for is quietly being dismantled by the same company that once depended on that ecosystem’s vitality to make its own product useful.

    From this vantage, Google’s summarization engine is parasitic, in the biological sense of the term: it requires a living host—the open web’s continuous production of new, verifiable, human-authored information—even as its design slowly starves that host of the resources needed to keep producing. A minority of publishers may survive by walling off their content entirely, blocking Google’s crawlers and rebuilding direct relationships with readers through subscriptions and newsletters; surveys already suggest roughly a third intend to try. But a web fragmented into paywalled enclaves is not a public sphere either. It is simply Googlization’s endgame arriving by a different road: a public information commons dissolved, whether by extraction or by retreat.

    Personalization only compounds the trouble. I spent a good portion of The Googlization of Everything worrying about the way Google’s ranking algorithm quietly tailored results to a profile built from your search history, your location, your device, your prior clicks, so that two people typing the identical query might receive subtly different worlds. Eli Pariser would later popularize this concern as the “filter bubble,” and the phrase stuck because it named something real: a public sphere that only pretended to be shared, since each of us stood in a slightly different room of it, seeing a slightly different arrangement of the furniture.

    Generative synthesis intensifies that condition in a way that personalized ranking never could. A ranked list, whatever its distortions and limitations, had discrete, checkable, external referents; you could, if you were curious, click past the first result and see what the second and third had to say. AI Overview offers no equivalent. Two users asking the same question may now receive two totally different yet confidently worded paragraphs, neither bearing any obvious sign of its own contingency, and neither offering the reader an easy way to notice that a different answer exists at all. There’s no way to study this phenomenon systematically, so no way to regulate it.

    One of the arguments I made in 2011, and the one I think holds up best, is that Google’s dominance was not merely a story of technical prowess or market cunning: it was a story of public failure. In the 1990s and 2000s, governments, universities, and libraries—the institutions that historically bore responsibility for organizing and preserving public knowledge—declined to, or were prevented from, building the digital infrastructure plainly required by an age when democracy seemed ascendant and universally desirable.

    We have traded a system that was biased and commercially distorted for one that is biased, commercially distorted, and prone to simply making things up.

    Into that vacuum stepped a private company with venture capital, engineering talent, and an advertising business model elegant enough to make the whole apparatus appear free. We got a useful tool and soon became too dependent on it. It was a tool answerable to shareholders rather than citizens, optimized for engagement and margin rather than for the health of the public sphere. Since then the public failure has only compounded, and with the tacit blessing of law.

    In August 2024, a federal court found, at long last, that Google had maintained an illegal monopoly in general search—a finding that vindicated much of what critics of Googlization had been arguing for a generation. But when Judge Amit Mehta issued his remedies in two rulings last year, he declined to order the most consequential structural fix available to him. He let Google keep Chrome, the browser that funnels a majority of the world’s search queries into Google’s own box, and he rejected a “choice screen” that might have interrupted the defaults nudging billions of people toward Google without a moment’s reflection. Instead he imposed modest adjustments such as a bar on exclusive distribution contracts and a requirement that Google share certain search-index and interaction data with competitors. These non-penalties arrived at the exact moment when the more urgent transformation in search—the move from links to synthesis—was already well underway, and the remedies say and do nothing about it. By the time the courts catch up again, the open web’s economic base may no longer be around to protect.

    When I chose the subtitle And Why We Should Worry back in 2011, I meant something more specific than free-floating anxiety about technology. I meant that citizens of a democracy have a stake in how knowledge gets organized, verified, and circulated—and that this stake is too important to be left entirely to the incentives of a single advertising company, however well-intentioned its engineers.

    This argument applies with even greater force to the present, because the stakes have moved from access to synthesis. Back then the worry was that Google decided what links you would see; today the worry is that Google decides what you read, in a Google-generated paragraph with no visible author and no stable citation trail—and does so at a scale, and with a fluency, that makes the underlying labor of the open web nearly invisible, even as that labor is being consumed to produce the answer. To be sure, the open web was never a commons—we shouldn’t get nostalgic for it. It was a mess of vitriol and scams peppered with some remarkable human expression; Google just hid the mess deep on the second page of links. Still, as nasty as it all was, it was better than what comes next.
    Image courtesy of Avery Dame-Griff
    The Scale’s the Thing

    Avery Dame-Griff

    When I grew up in the mid-1990s there were always two computers in our house: one for my father, a systems administrator, and one for me, always one of his hand-me-downs. One such specimen is captured in the photo above, taken in December 1995. The machine wasn’t exactly top-of-the-line, but for a seven-year-old it was a pretty nice setup. Thanks to my father’s job, we also had a home internet connection much earlier than many of my peers did. I remember us sitting side-by-side on weekend nights, him working through an issue with a work server while I was talking with strangers online in random chatrooms.

    If you used enough early text chat, you’ll remember one of the most common questions from that era: “age/sex/location?” or, as it quickly became abbreviated, “a/s/l?” The query originated earnestly enough—a way for others to learn more about you and find points of connection—but at some point I had a realization: I could lie. No doubt, many did. I never lied outright, because I’ve always been a bit of a rule follower, but I did spend much of my youth online avoiding any reference to or mention of my gender. People just assumed I was male, and I did nothing to disabuse them of the notion. Looking back, I recognize this habit as part of my larger trans experience. Once I became friends with trans folks online, I began to understand the discomfort I felt with having to reveal my “real” gender: the online was, in fact, my “real” gender.

    Our current internet landscape has a totally different scale—we are connected to more people than ever before, and yet we are profoundly isolated from them.

    For years I’ve been collecting memories of the early internet. I’ve heard about lifelong friendships begun on mailing lists and forums, emails that kept couples connected before cheap long-distance calls, the passive aggressive navigation of teen friendships via AIM away messages, the forging of bonds over voice chat while gaming. The breadth of formats highlights just how much digital communication has evolved over the past forty years. We don’t hear much anymore about the Bulletin Board Systems (BBSes) that closed en masse in the mid-1990s when Americans embraced the World Wide Web. The once-omnipresent America Online—better known as AOL—survived the shift to WWW only by abandoning its walled garden model and becoming just another internet service provider. On the Web, a variety of digital spaces had their moment—message boards, Yahoo! Groups, LiveJournal—until first Facebook and then other social media companies slowly absorbed all communication online. Usenet, first launched in 1980, hung on longer than most, but by the 2010s the number of active communities had shrunk drastically.

    I think it’s no coincidence that all these memories, my own included, are of organic interactions online, often at a small scale. Those of us who experienced the earlier days of the internet seem to be fondest of the small moments when we made a surprise connection or learned something about ourselves—usually in the small, often volunteer-managed digital communities that fostered strong interpersonal connections, both online and off. Folks who first met on local BBSes, mailing lists, or Usenet often connected at regular in-person get-togethers. The possibility that you might have to face someone at next month’s meet-up created a very different social dynamic: you might be less likely to flame them, among other things. Our current internet landscape has a totally different scale—we are connected to more people than ever before, and yet we are profoundly isolated from them.

    The story of this transformation has been told many times, and shifting incentives are a big part of it. As Megan Sapnar Ankerson discusses in Dot-Com Design (2018), commerce drove popular adoption of the Web once most users could access visual browsers like Netscape. After the dot-com crash of the early 2000s, e-commerce became even more of a focus as companies scrambled to find new ways to recoup their losses. Looking at popular media coverage from the era, one sees a slow but unmistakable shift in depictions of the internet user from communicator to consumer. The Web was “the greatest social revolution since the automobile,” Popular Mechanics declared in 1994. And just as cars drove the growth of suburban shopping malls, the internet would stoke consumption—and advertising for consumption—in ever-greater amounts.

    Key to all this was reducing friction: those moments online that require users to slow down, consider why they’re doing something, or take real effort to complete a task. Everything is faster, easier, and less mediated now, and we’re still grappling with the change. As technology scholar Jason Farman recently argued in Slate, “frictionless design has helped usher in technologies that manipulate behavior in ways that aren’t always visible to us” and “mask systems that we neither understand nor control.” Journalist Ryan Broderick has dubbed this moment the Clear Channel Internet, “where everything has been so thoroughly corporatized that nothing ends up in our feeds by accident anymore.” While Broderick’s focus is viral content, I would extend his framework to the modern internet platform per se. Tune in to any iHeartMedia station; no matter the genre, the listening experience is frictionless. It may not be exactly to your taste, but it’s consistent and predictable. It isn’t exactly Muzak, but it’s no Vintage Obscura Radio. Most important, it’s all advertiser friendly: last year iHeartMedia controlled 40 percent of radio ad revenue in the United States.

    After two decades of innovation in digital attention-mongering, all the major social platforms today function on the same principle as mass media: keep the user engaged as long and as frequently as possible in order to sell ads. Along the way, frictionlessness has been extended from design to user-generated “content” itself. Platforms today want content that keeps users engaged (including through outrage) but isn’t so enraging or uncomfortable—doesn’t create too much friction—that it drives them away or alienates advertisers.

    Of course, what counts as the wrong kind of affective friction, and for whom, has fluctuated over time—a function of changing social norms, commercial incentives, and political realities—but digital queer existence has always been precarious. LGBTQ communities were only tentatively embraced in the mid-1990s once platforms realized they were a possible source of revenue. When our appeal as a targeted ad market dries up, we become a kind of industrial byproduct that platforms can repurpose to fuel more user “engagement.” Last year Meta’s Chief Marketing Officer and VP of Analytics, Alex Schultz, went so far as to present this repurposing as an opportunity to shore up LGBTQ rights. Defending the company’s new, vastly pared-down moderation and hateful conduct policy—which among other things now permits users to post “Trans people aren’t real” and “They’re mentally ill”—Schultz wrote in an internal post, “I personally feel that actually the shock of friends and family seeing me receive abuse as a gay man helped them understand the hatred that exists and hardened support.” In this calculus, frictionlessness becomes one group’s prerogative over another: bigots enjoy the comfort of a seamless platform experience, while their targets are asked to experience a little friction and suffering in service to their cause.

    Indeed, the only time social media platforms introduce friction these days is when they want to discourage users from producing content, and they increasingly rely on automated systems for content moderation for two reasons. First, the sheer scale of content produced is massive, so automation reduces the burden on content moderators. Second, decisions made by automated systems don’t introduce the same level of friction. Humans want to make the right decision, so sometimes we take our time to consider the situation. (This experience is perfectly captured by the game Moderator Mayhem.) Of course, users are typically given the option to appeal a platform’s moderation decision, but the process is labor-intensive and opaque, and you never get to talk to a human. Intentionally or not, the process thus deters users from making an appeal—it’s easier just to accept the decision and try making your posts more platform-friendly, if you can see how. But some users encounter so much friction it’s just easier to avoid talking about unapproved topics altogether. Last year one reproductive health group was reportedly advised by a Meta employee “to simply move away from the platform entirely and start a mailing list,” since “bans were likely to continue.”

    Like contemporary platforms, the utopian comfort of Le Guin’s Omelas is only possible because someone else suffers.

    Meta denied sending this message. But as I consider what our online future could be, I think of this warning and am reminded of the ending of Ursula K. Le Guin’s classic short story, “The Ones Who Walk Away from Omelas.” Like contemporary platforms, the utopian comfort of Omelas is only possible because someone else suffers—in this case a single child, living forever in darkness and misery. Everyone learns this at a certain point and must make a choice, to stay or leave forever for the unknown: “The place they go towards is a place even less imaginable to most of us than the city of happiness. I cannot describe it at all. It is possible that it does not exist. But they seem to know where they are going.”

    But it’s not enough simply to walk away from today’s version of social media. In Afrofuturist N. K. Jemisin’s story “The Ones Who Stay and Fight,” there is no exploited child in the utopian city of Um-Helat. Instead, there are social workers whose sole job is to keep anti-utopian ideas like inequality and exploitation from entering society. While suffering is not fully eliminated in Um-Helat, its citizens prioritize the good of the community. Jemisin says she conceived of the story as a response to those who interpret “Omelas” as advocating totally abandoning current capitalist society—something impossible for those without generational wealth and with “nowhere to walk away to.” Um-Helat remains a utopia “as long as they keep at bay the idea that somebody’s got to suffer.”

    I don’t have one all-encompassing prescription for my vision of a future better internet. What I know is that our current digital landscape wasn’t inevitable. A healthier social ecosystem online is possible. When our infrastructure is oriented toward the small scale rather than toward growth at all costs, we get those internet memories people have shared with me over the years—talking one-on-one, getting to really know and care about each other. There will always be friction when we interact and build community; the goal can’t be to eliminate it altogether. Rather, we should recognize how it can productively strengthen our investment in each other. Walking away is just the first step on the path to a different future we must collectively make together.
    Detail from cachemash #185. Image: Hugh Manon via Flickr
    Net Positives

    Joanna Walsh

    It was 2014, and I hadn’t yet published my first book. I opened my email app and wrote to the editor of 3ammagazine.com, an online literary journal:

    You have a great mag but I can see you don’t have a dedicated fiction editor and, though you regularly publish fiction, the mag doesn’t have a consistent approach. How about you appoint me as fiction editor and I can fix all that?

    Or something like that. I could search for the original email, but something tells me not to try. This kind of hubris only made sense on a web that no longer exists. Maybe I’ve changed; or maybe the internet has, or maybe it’s the position of independent online literary magazines.

    I’d never met 3:AM’s founder, British writer Andrew Gallix, IRL, so I was surprised when the head of a journal whose tagline is “whatever it is, we’re against it” wrote back and said yes. The few bylines I had were mostly for unpaid work in free online mags. I was new, I had hope, and I worked hard. I wrote calls for submissions, read slush piles, selected work, wrote rejection and acceptance emails, edited and uploaded pieces, designed pages using HTML, sourced artwork (forming relationships with artists), and publicized the work via the mag’s social media accounts. I published two stories a month, which may not sound like much, but it took up a lot of my time and I worked for free.

    On Twitter, I met friends, lovers, allies, enemies, funders, and employers. It was this atmosphere that made me believe, for the first time, that my writing might be published, might be read.

    Never work for free, I hear from many fellow writers now. And they’re right. Sort of. I’d say, never work for free for anyone who’s being paid to produce any product they’re going to charge for. Never work for free to produce something that can be produced commercially. What I did at 3:AM was outside that. Because we couldn’t pay I made a commitment not to run anything I could imagine being published in a commercial venue. (Not so) sadly I was wrong: I published experimental writers, some of whom not only went on to be published in the mainstream, but who changed what the established world of literary fiction could be. I published early work by Eley Williams (who went on to be my 3:AM successor) and Isabel Waidner. I’m proud of what I did there.

    Why did I do it? Like most artists, for mixed motives. I wanted to create a space of a particular kind, a space I didn’t see elsewhere. Like the writers I published, I also wanted to expand my chances of being published in the world of paid writing. What 3:AM offered, what I offered—to them, to myself—was a chance to dodge some of the gatekeepers of the mainstream literary world.

    I “became” a writer on early Twitter, which I joined in 2008. I had been working as an illustrator and ran a drawing blog, which eventually became more writing than drawing and, though it managed to win a few awards, I had no education in writing, no contacts, and, with full-time care responsibilities and limited financial resources, little chance to attend readings, form connections, or get anywhere near any literary scene. But back then, online was a scene. Twitter was a largely uncommercial space, but it already had enough subscribers for me to connect with publishers, published writers, and writers who were just starting, who swapped reading and publishing recommendations, advice, and support—writers like me. It was crucial that I met the whole range because any emerging writer needs both peer support and opportunities. On Twitter, I met friends, lovers, allies, enemies, funders, and employers. It was this atmosphere that made me believe, for the first time, that my writing might be published, that my writing might be read.

    2014 was a long time ago in internet years. What has changed?

    With the enshittification of social media, particularly Twitter, where so many writers found a natural home, the algorithm now fails to deliver a predictable feedback loop. Tweets from accounts with tens of thousands of followers are downlisted unless the account-holder pays. But, with no advertising budget and no built-in reach, indie literary mags depend on social media. Tobias Ryan, an editor of minor literature[s], a “collaborative and not-for-profit” online journal, told me that “changes at Twitter in particular made maintaining a presence there more difficult and finding an audience almost impossible. They deactivated Tweet Deck, which logistically made things harder to manage, as well as blocking automatic tweets through WordPress, who host minor lits. That just made everything more difficult/time consuming.”

    As platform owners consolidate and monetize, they also limit links that take readers offsite. “Algorithms changed to de-prioritize external links,” says Ryan, “with the aim of keeping users on site, so views fell through the floor.” What’s more, “when Musk took over people didn’t want to be on Twitter anymore (intensifying after the Trump election in 2024). First people fled to Mastodon, then Substack, then Bluesky—what had been a pretty coherent audience splintered. It became necessary to keep up multiple accounts, none of them garnering the views and interactions Twitter once had.”

    Today there may be more of what the art theorist Claire Bishop calls “disordered attention,” due to a bewildering proliferation of platforms hosting huge volumes of both human and AI-generated “content,” but the open web is shrinking. Where search engines once provided a list of links to human-written articles, many readers are now content with an AI summary. But to blame readers, or even platforms, would be to offload responsibility for a deliberate and politically motivated war on the arts and humanities by governments and institutions across the English-speaking world.

    The withdrawal of grants from independent publishers and magazines—particularly Trump’s devastating cuts to the National Endowment for the Arts, which supported so many independent venues for publication, online and offline—means that authors have to look elsewhere for income. As state support dries up, writers are back in the age of the patron—or, rather, Patreon. To paraphrase the well-worn quote: Times are bad, children no longer obey their parents, and everyone is writing a Substack. The original line is usually attributed to Cicero and sometimes even to Socrates. Search Google Books and it comes up in plenty of volumes (including many published pre-internet), though none by Cicero—an indication that the pre-AI publishing world was not so different from our own.

    But if fake quotes existed before AI, editors now have to wade through ever-enlarging submissions piles that aren’t only slush but slop. This year Granta withdrew from its partnership with the Commonwealth Short Story Prize after unconfirmed speculation that this year’s winning story was AI-generated. The publishers of some indie magazines, already engaged in a labor of love, are losing trust in their submissions, and losing heart.

    Even pre-AI the slush piles were getting bigger. There are more MFA grads now than there were in 2014, though U.S. and U.K. governments are doing their best to fight this, axing arts and humanities degrees even when they run at a profit. This slashing of liberal arts departments deprives the world not only of writers but critically engaged readers.

    What does this mean for emerging writers now? Paywalls are going up again. Panicked by AI, underfunded traditional publishers are shutting the gates to new writers, and those gates are being kept. Literature is being re-professionalized, and too much of the little space that remains can only be occupied by writers with the connections or money to buy the time to stay in the game.

    The opportunity to participate in the arts, not only as spectator but creator, was the promise of Web 2.0. It was a promise very imperfectly kept, but one we must remember.

    A number of them will be excellent writers, so what does this matter? The narrower the social source of stories told in any medium, the more people are excluded from our political and social imaginary—the right to “main character energy.” Having our stories told for us, however expertly, by a narrower social cohort, is no compensation. We need a culture that allows us to see each other, and that also allows us to see ourselves.

    The right to create our own culture doesn’t automatically fix politics. But the right to creative expression not only facilitates human rights: it is a right in itself. It is something humans do, and its limitation is a form of oppression. Why else do so many people who can make money elsewhere still dream of writing, painting, making films, and still use that money to pursue those dreams? In the current climate, writers, editors, and readers will have to look to ways of writing, publishing, and reading beyond the mainstream and beyond the monetized or monetizable.

    The net is still a resource. Remove the net and you remove chances for writers whose work is considered too marginal, or who are too personally marginalized, to easily enter the mainstream. Ryan is concentrating on IRL events: “in the context of online entropy,” he says, “it’s good to be with people and share moments, but. . . . Doing things in-person is probably no better or worse than doing things digitally. Our guiding line has always been wanting to make stuff happen with the people whose work we like and respect. That’s what we would consider a net positive.”

    It remains an internet positive. The opportunity to participate in the arts, not only as spectator but creator, was the promise of Web 2.0. It was a promise very imperfectly kept. But to fight for a future expansive arts culture, it is necessary to remember and understand what has been achieved.
    Image: Gino via Flickr
    That Obscure Object, Desire

    Chad Wellmon

    It’s true: I miss the old Google Search results page, bare but for its blue links and a few ads. For a fleeting historical moment, Search seemed to make real that old dream of a universal library, providing smooth passage to archives, books, and databases—the kinds of learning I’d always coveted. It was both a pathway through the open expanse of knowledge and a portal to surprise, a tool for figuring out what you didn’t know you didn’t know and where and from whom you could find it. So significant was this experience for so many that to search, for a time, simply was “to google.”

    Looking back on a quarter century of Google Search and wondering what to make of its AI successor, I can appreciate, if not affirm, my nostalgia. In those blue links I saw footnotes, and in the ranked results I saw discernment; when I first encountered Google as a graduate student in the early 2000s, I recognized something of the self I was working to become and the institution I thought would get me there. Google cultivated this identification with scholarship and the university; its two founders, while in graduate school themselves, even contrasted “advertising oriented” search with their own efforts in the “academic realm.” But now that intellectual work and knowledge institutions are everywhere under threat, the company too, it seems, has moved on.

    Liz Reid, Google’s head of Search since 2024, recently described the earlier results page as a “construct,” a response to an older Web built upon webpages, links, and documents. Google’s newer “intelligent” search responds to a very different Web, and a different division of labor and knowledge. The company’s goal is no longer to point us in the right direction—to orient us in the vast public conversation that is hypertext, to set us off on open-ended inquiry with others—but to close the loop of our own intellectual desires by guessing at what it is we want and giving it to us all on its own. Where Search was once a matter of pointing, it is now a matter of presentation.

    We’re only just beginning to understand the consequences of this shift. What I’ve realized belatedly, myself, is that things were headed this way all along.

    To appreciate what Google accomplished, you have to imagine a world not yet saturated by search. Before the explosive growth of the Web in the mid-1990s, document collections and databases were comparatively bounded, centralized, standardized, homogeneous, and organized—the province of experts and professionals, searchable through specialized syntax, typically with the help of technical mediation. Even early automated information retrieval systems, such as Cornell University’s System for the Mechanical Analysis and Retrieval of Text (SMART) of the 1960s, assumed relatively well-controlled collections. The early Web, by contrast, was distributed, fragile, heterogeneous, and, if at all, only locally organized. Its documents differed not only in language and content but also in format, style, size, and trustworthiness, and they could be queried not only by experts but by general users.

    In those blue links I saw footnotes; I recognized something of the self I was working to become and the institution I thought would get me there.

    These very features that made the Web exciting—openness, decentralization, proliferation, the lack of gatekeepers—also provoked fears of disorder, excess, and unreliability. Jon Kleinberg, a computer scientist at Cornell, expressed this ambivalence in 1997 when he called the Web an “intricate form of populist hypermedia.” He stressed the need for a filter to determine “authoritative” and “definitive” documents. But how could authority, quality, judgment, and value be conceptualized in the anarchy of the Web?

    This problem was answered—in Kleinberg’s own HITS algorithm, and Sergey Brin and Larry Page’s PageRank—by adapting the quantification of academic citation developed by figures such as Eugene Garfield, Francis Narin, and Gabriel Pinski, who founded the field of bibliometrics in the 1960s and 1970s. Within this new search paradigm, a page was judged important if it was linked to by other important pages; authorities were identified by hubs, and hubs by the authorities to which they pointed. No claim was made about the truth or intrinsic value of particular pages. Instead the importance of a page was measured by its relation to other pages, mining older standards of legitimacy—expertise, scholarly review, cultural authority—from link structure.

    In this way, PageRank quantified the social judgments assumed to be latent in the Web itself. This founding ideal fit a moment when garbage hadn’t yet overtaken the internet—when the quality of the average webpage was relatively high and trust in institutions hadn’t collapsed. It offered a distinct advantage over human-curated or keyword-based search engines—like AltaVista and Yahoo!—at the same time that it disciplined the “populist” Web, holding out the promise of an objective, neutral, and trustworthy technique for taming digital disorder.

    From this vantage, Google’s recent embrace of “intelligent” search is less of a rupture than it might seem. Instead of a reversal of its original project, it’s an intensification of it. From the start, Google treated the Web less as a collective good, a public library or scholarly commons, than as a vast and unruly data source that could be transformed into property and profit. Though it welcomed comparisons to libraries and universities, Google was never either of these things, and never capable of sustaining the distinctive practices and values of scholarly communities. It was always a highly capitalized, competitive business in the market for data at scale.

    And yet, it’s not surprising that Kleinberg, Brin, and Page would see in Web links a version of academic citation. Bibliometric citation analysis itself emerged as a response to another crisis of information overload: the postwar proliferation of scientific literature and the ascendance of Big Science. By tracking citational chains—who cited whom—and converting those relations into quantified metrics, citation analysis helped scientists decide what to read and help the federal government and universities decide what to fund. Google adapted this logic to the Web: like its bibliometric forebears, as historian Kevin T. Baker has explained, the company converted a marker of intellectual relation into a simplified measure of value.

    I didn’t understand this at the time. What Google offered was a familiar form of authority, one that reminded me of older ways of searching. Already overwhelmed by spam and big banner ads, I wanted a Web that was as orderly and accessible as the libraries and journal collections I browsed. Just as the orderly arrangement of stacks didn’t rule out spontaneity, clicking through links served up by Google felt like following footnotes, tracing paths through an index that both organized and surprised. In reality, the system was increasingly governed by captured values. Garfield’s “solution to the problem of scientific information overload,” Baker writes, “became Google’s solution to the problem of internet information overload, and it was gamed in the same ways.” Since citation became synonymous with “credit” and “endorsement,” the metric became a goal in itself. The result, Baker observes, was to generate ever “tighter feedback loops.” The system Google built to organize the Web begot the very thing that exhausted it: SEO.

    Like academic citation systems, PageRank was recursive: it grounded authority by referring to already recognized authority. That recursion could appear legitimate as long as the social institutions and systems behind it were trusted. Once that trust weakened, the same logic began to look less like social discernment than like capture. As the postwar liberal consensus about the value of higher education—that it is a good too good to be questioned—continues to erode, the appeals of universities to their own internal measures of academic prestige and disciplinary expertise (academic rankings, publication numbers, citation counts, prizes and honors) can seem less like manifestations of a professional judgment that demands public deference and more like just another example of elite self-interest.

    But there was a key difference. Unlike universities and institutional science, Google recognized early on the threat that value capture posed to search. Its own skepticism about the PageRank ideal and the Web itself pushed it beyond the document-centric model. The ideal search engine, Brin suggested, would not merely process and organize the world’s information; it would “understand” us and give us what we want. The perfect search engine would not model the Web. It would model us. “We’re really making an AI,” Page reportedly told tech journalist Kevin Kelly in 2002.

    Over the next two decades, as Google made good on that confession, the company steadily abandoned the PageRank ethos, turning its search engine into a complex, constantly changing system of algorithms, databases, and human interventions. Predictive text systems such as “Did you mean . . . ?” (2001) and autocomplete (2004) treated search not as fixed-token matching but as correction, prediction, and inference. Caffeine (2010) and Panda (2011), among the most significant updates to Search, conditioned relevance and value on a range of new variables: freshness, location, user behavior, query reformulations, human raters’ judgments, and other proxies. Then came the Knowledge Graph (2013), with more than 500 million objects and more than 3.5 billion relationships. Results pages began to display knowledge panels, summaries, key facts, and related entities. Searchers no longer had to visit and compare websites beyond Google; Google itself delivered a ready-made synthesis with its own proprietary semantic infrastructure. PageRank remained a signal in all this, but authority came increasingly from data that Google accumulated, organized, and evaluated.

    “Let Google do the searching for you” is telling us the Web is too degraded, our institutions are too untrustworthy, and we ourselves are too exhausted to search. Maybe we are.

    By 2017, in the wake of Trump’s first election, Google’s transformation of Search was converging with talk of disinformation, “fake news,” and a more ambient crisis of trust in a “post-truth” era. In response to always-evolving attempts to “game” the system, Google promised “structural” changes: revised Search Quality Rater Guidelines, more human evaluation, and adjustments to the signals feeding its ranking systems. Later that year, Google researchers published their influential Transformer paper (aptly titled “Attention Is All You Need”), introducing what would become the technical hinge between earlier iterations and LLM-based search. Traditional search, Google engineers summed up in a 2021 paper, imposed artificial restrictions by offering references to documents rather than directly answering information needs. It subjected users to an unnecessary and “significant cognitive burden.” Google should aim, they concluded, no longer to improve the index—to contribute to the health of the Web by making it navigable—but to transcend the indexical function of search itself. Today’s AI-driven “intelligent” search encloses the labor, judgment, and intelligence of the Web within a consumer interface that can generate answers directly—and capture the value of doing so.

    The promise to “understand exactly what you want” and “give you the right thing” makes this transformation explicit. We sometimes know what we want, but often we don’t; indeed the most satisfying and fruitful inquires often begin in ignorance. Google presumes either that our desires are already clear and that it can satisfy them more efficiently, or that it knows our desires better than we do. In either case, AI search keeps us enclosed within the frictionless, decontextualized domain of this privately owned attention leviathan—all the better to capture and monetize the social knowledge and labor on which it depends.

    The all-in pivot to “intelligent” search thus marks much more than a technical innovation. It belongs to a broader crisis of epistemic authority, institutional ruin, and social conflict across the whole of U.S. society—the universities, newspapers, libraries, community and civic organizations, and other social structures that knowledge creation and dissemination rely on. When one of the richest companies in the world implores, “Let Google do the searching for you,” it is telling us that the Web is too degraded, our institutions are too untrustworthy, and we ourselves are too exhausted to search. Maybe we are. But we should be clear about what this entails: the conversion of public crisis into private profit.

    Those classic blue links reminded me of the unambitious, prosaic intentions of much earlier search technologies, from early modern indexers and commonplacers to twentieth-century documentalists, librarians, and information retrieval specialists. These figures understood search as the cultivation of particular practices within particular communities. Compared to the epochal pledges of Google, Open AI, and Anthropic, their ambitions may seem mundane, but they helped sustain shared cultures of knowledge production that remain worth sustaining today. Search, in this sense, has always meant an open-ended exploration that propels people beyond themselves and their own settled desires toward the possibility of intellectual surprise and ends that aren’t already fixed.

    The history of search is full of warnings: the index is not the book, the footnotes aren’t the page, the map is not the territory. At the core of these admonitions is a fear that search might come to substitute for reading, writing, thinking itself. The PageRank ideal, despite its limitations and eventual failures, preserved something of these older practices. It rested on a reasonable premise: search technologies can aid but cannot replace the messy, context-bound, all-too-human creation of knowledge. With the collapse of that shared premise, the old fears have a new and very real target.
    Image: Getty Images
    Managed Decline

    Cory Doctorow

    If I want to make myself really angry about the enshittified state of the internet, I don’t fume over pages of slop-drenched, spam-drowned Google results; nor about the fake-review garlanded sub-Temu garbage on Amazon. I don’t even rage against Elon Musk’s child porn–choked, bot-infested Twitter.

    No, when I want to get good and apoplectic about the internet, I think about policymakers. Specifically, I think about all the policymakers I’ve met and corresponded with and begged with and pleaded with and raged against in my twenty-five years with the Electronic Frontier Foundation.

    These policymakers are the true authors of our misery. It was they who made decisions that had the foreseeable and foreseen outcome of ushering in the enshittocene, this era in which all of our technology is turning into shit. The thing is, we told them exactly what would happen if they made those policy blunders, and they made them anyway, and now they walk among us, disclaiming any responsibility for systematically rigging the game so that the worst people with the worst ideas make the most money.

    It was policymakers who made decisions that had the foreseeable and foreseen outcome of ushering in the enshittocene—this era in which all of our technology is turning into shit.

    It’s as though we used to put down rat poison, and we didn’t have a rat problem, and then these guys told us that we had it all wrong and we didn’t need the rat poison after all. Now, rats are eating our faces off, and these guys refused to accept that their pro-rat policies had anything to do with it. They say we’re living through the Time of the Rat, in which the great forces of history and the iron laws of economics have combined to create rats of unheard-of fecundity. When we point out the rats have bought and shuttered the rat poison factories, they get defiant: “So what? We’re not using rat poison anymore. That’s just economically rational!”

    Take competition law. Forty years ago, Reagan’s economic advisors from the Chicago School declared that monopolies were efficient. In other words, if you arrive at a juncture in which everyone buys the same products from the same firm, you should conclude that we all just love that company’s products so much that we’ve flocked to them. If you accept this premise, well, then it would be perverse to use public resources to punish that company.

    So we just. . . stopped. For decades, we allowed companies like Google and Facebook and Amazon to violate competition law. We let them buy their major competitors, and we let them swallow up any small company that might eventually become a competitor. We let them engage in “predatory pricing”—selling goods below cost in order to drive rivals out of business. We let them tie up retail channels with exclusivity deals, and we let them tie goods and services together. All of this is plainly illegal, but because we were told “monopolies are efficient,” we sat back and watched as these companies violated the law and captured their markets and turned the internet into five giant websites, filled with screenshots of the other four.

    The thing is, a company that’s too big to fail is also too big to jail. Once these companies captured their markets, they also captured their regulators. When a sector has a hundred medium-sized companies in it, it is eminently governable. All those competitors erode each other’s margins by raising wages to attract the best workers and by lowering prices to capture the most customers. That leaves them with precious little surplus capital to piss away on regulatory adventures—and even when they turn their efforts to lobbying, they can’t possibly sing with one voice. You can’t get 100 companies to agree on anything, much less a regulatory agenda for their industry.

    But when an industry cartelizes into a handful of companies, they find it trivial to capture their regulators. In 2024, Joe Biden’s Federal Trade Commission finalized a rule called “Click to Cancel” that banned the practice of making it very easy to sign up for a service but nearly impossible to cancel it (and the recurring bill it sends to you). In 2025, Donald Trump’s FTC let the rule die. Trump enjoyed the backing of the Wall Street Journal, which ran more than a hundred editorials condemning Biden’s generationally talented FTC chair, Lina Khan. While the Wall Street Journal isn’t the only firm that benefits from the death of Click to Cancel, it does have one of the internet’s most egregiously byzantine cancellation processes.

    Think of how tech giants spy on us all the time and use the data to hurt us in terrible ways. The totally unregulated data-broker sector lets predators target marketing categories like “seniors with dementia” and sell credit card history to nursing agencies that use it to lower the hourly wages offered to the most indebted workers.

    Why does the data-brokerage industry exist? Because it can. Congress hasn’t passed a new consumer privacy law since 1988, when Reagan signed a bill making it illegal for video store clerks to leak your VHS rentals. Every form of privacy invasion invented since Die Hard was in cinemas is legal. That’s what regulatory capture looks like.

    If they weren’t beholden to the power of industry, policymakers could have passed a privacy law at any time in the past thirty-eight years. It’s not like there was a shortage of things to regulate. From deepfake porn to kids being targeted by social media algorithms to racial discrimination in online housing, lending, and job markets, the failure to pass a privacy law for two generations has inflicted enormous pain on hundreds of millions of Americans while making a small number of corporate executives very, very rich.

    Regulatory capture isn’t just about preventing laws that get in the way of profits. A sector that captures the regulatory apparatus becomes fused with the state. In fact, tech giants don’t just exercise power over the law; they also enforce law, but only against smaller, newer tech companies that are small and scrappy enough to care whether you like their products. Tech’s favorite weapon here is a bizarre kind of intellectual property law called “anticircumvention.” Under this regime, it is illegal to modify a device that you own if the manufacturer has decreed that the device must not be tampered with. America got its anticircumvention law in 1998 as Section 1201 of the Digital Millennium Copyright Act (DMCA 1201), which established a new felony for “bypassing an access control” that carries penalties of a five-year prison sentence and a $500,000 fine for a first offense.

    What this means is that if a digital device that you own is designed to steal your data and/or your money, you are not allowed to alter that digital device in order to protect yourself. Apple blocks Facebook from spying on iPhone owners, but it gathers exactly the same data that Facebook wants, using the phone it sold you, and uses that data to target ads to you. Thanks to anticircumvention law, it is a felony for me to sell you a software patch for your iPhone—the phone you paid $1,000 for, which belongs to you—to stop Apple from stealing your data.

    America got its anticircumvention thanks to the efforts of Bruce Lehman, who was the Clinton administration’s intellectual property czar. When Lehman proposed this law, he was laughed out of the room. So, in Lehman’s own words, he did “an end-run around Congress” by going to the United Nations and getting anticircumvention law embedded in a treaty. Congress then passed DMCA 1201 in order to bring the United States into compliance with this treaty obligation.

    Lehman was warned at the time that making it illegal for you to decide how you used your own property was a nightmare scenario—in particular, that it would encourage companies to lock their products to consumables (which is how we got $10,000/gallon printer ink); to dominate markets for complementary goods (which is how we got app stores that limit which software you can install and charge the providers of that software thirty cents on every dollar you spend in their apps and games); to lock out repair, to spy on us, and to downgrade their products after we buy them and then charge us subscription fees to use the features that came bundled with the product when we bought it. In short, Lehman was warned that anticircumvention was a moral hazard, an attractive nuisance, a license to enshittify with impunity . . . and he pulled out every stop to get it through Congress anyway.

    These are the things I dwell upon in my dark hours. Not the moral deficiencies of the ketamine-addled Zuckermuskian mediocrities who’ve appointed themselves our permanent tech overlords. Awful as those men are, they are merely behaving in ways that the policy environment both permits and encourages. They are not the ultimate causes of enshittification: they are the effects of an enshittogenic environment. Force them out and they will be replaced by someone every bit as awful.

    Nor do I dwell upon you and your deficits. I categorically reject the idea that the internet turned to shit because you chose the wrong services. Anyone who says, “If you’re not paying for the product, you’re the product” is helping Big Tech rip you off and ruin the world. Giant companies don’t abuse you because you don’t pay them enough money. They abuse you because they can get away with it, and if you pay them and they can get away with making you the product, then they’ll make you the product anyway. A company that is too big to fail and too big to jail will always be too big to care.

    Awful as the ketamine-addled Zuckermuskian mediocrities are, they are not the ultimate causes of enshittification. They are the effects of an enshittogenic environment.

    If we bear any responsibility as individuals, it is this: sometimes, we are foolish enough to buy into the excuses for enshittogenic policies and support them. DMCA 1201 was supported by many advocates for creative workers, who thought that banning circumvention would stop people from pirating media. It absolutely, categorically failed to do this (as was foretold at the time), but for people who had a problem, any solution—even a backwards, ineffective, harmful one—was something worth promoting.

    And it keeps happening. In the decade since Trump signed SESTA/FOSTA, a bill nominally aimed at preventing sex trafficking by making online publishers liable if their platforms were used by pimps and other odious creatures, platforms simply banned anything remotely pertaining to consensual sex work, forcing sex workers out of the space where they screened clients and back into the street. Pimping, long in retreat, is now a growth industry again; sex trafficking is still alive and well. No one heeded the warnings about the obvious, foreseeable outcome of this badly conceived non-solution to an actual problem. Instead, we embraced the politician’s syllogism: “Something must be done. This is something. I am doing it.”

    Today, many people who have good reason to hate Big Tech have thrown their lot in with a new enshittogenic policy: age verification. “Age verification” doesn’t exist. There is only identity verification: that is, strongly tying every packet sent or received on the internet to the real-world identity of living people. Children have lots of problems with the internet, but these problems will not be solved by requiring the most enshittified tech platforms in history to gather and retain even more data about everything they do—and everything everyone else does, too, just in case we turn out to be under age.

    It’s not good enough. The internet is the system we use to wire together the world, the communications tool we will need to fight back fascism, survive the climate emergency, and end genocide. We can’t afford to make common cause with the policymakers who don’t care how enshittogenic their ideas are, so long as those ideas are politically expedient.

    #Internet #Media #Technology

    #médias #capitalisme #Sachzwang #monopoles #www #web_2 #AI #histoite #bibliothèques #GAFAM #politique #Charaktermaske

  • L’IA dans les formations supérieures : beaucoup d’effets délétères et peu d’apports positifs

    D’après l’enquête IA et enseignement supérieur réalisée par le MESR en juin 2025 (https://mission-ia-sup.forge.apps.education.fr), les usages pédagogiques de l’IAG (Intelligence Artificielle Générative) largement dominants dans les universités sont de l’aide à la rédaction (44% des usages pour les enseignant·es et 62% pour les étudiant·es) et la recherche d’information (75% pour les étudiant·es). En termes d’outils d’IA souhaités, la recherche d’information arrive en rang 1 avec 60% des étudiant·es, à quoi s’ajoutent 50% de recherche de sources diversifiées (rang 4) et 50% de vérification d’informations (rang 2). Le rang 3 est occupé par l’assistance à la rédaction. Il n’y a donc pour l’instant aucun doute sur les usages actuels de l’IA et leur avenir proche par les étudiant·es. Pour les enseignant·es il s’agit surtout d’aides à l’évaluation (les 5 premiers rangs, supérieurs à 50%).

    Réaliser soi-même la recherche d’information et de rédaction est essentiel dans une formation supérieure

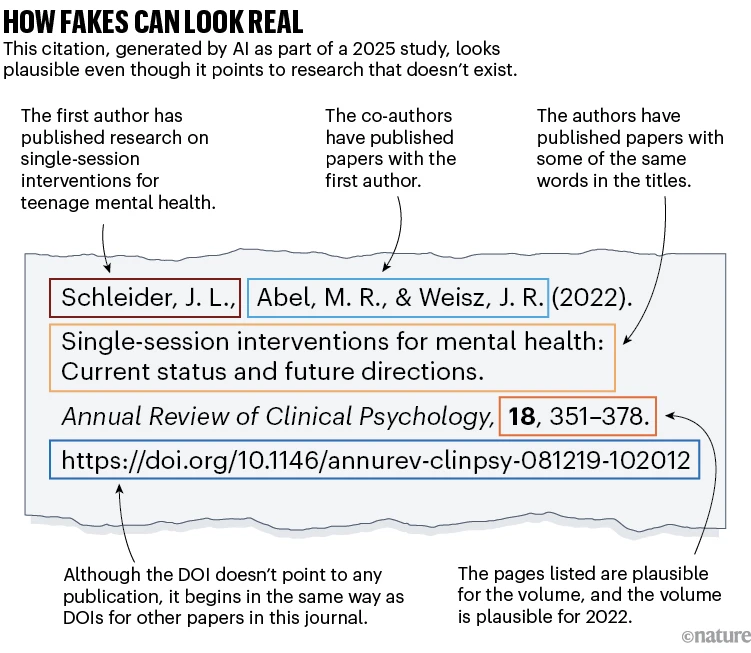
    Or ces usages touchent au coeur même des activités d’#apprentissage, fondé, dans le supérieur, sur des méthodes rigoureuses issues de la #recherche_scientifique (Voir aussi : https://www.polytechnique-insights.com/tribunes/digital/lia-generative-bouleverse-t-elle-les-pratiques-pedagogiques). Il est crucial d’apprendre à chercher et identifier les #sources, les vérifier, les comparer, les valider. Les étudiant·es demandent la plupart du temps à l’IAG de faire ce travail à leur place, n’apprenant donc pas à le faire. Pire : l’IAG est un intermédiaire qui masque les sources, d’autant que les outils d’IA gratuits qu’utilisent les étudiant·es offrent des possibilités limitées. On voit ainsi souvent des #bibliographies fictives, où une IA a associé des noms d’auteurs et d’autrices réels avec des titres d’ouvrages réels ou probables chez des éditions vraisemblables sauf que ces ouvrages n’existent pas : l’IAG a combiné des éléments probables. Exemple vécu : dans une #bibliographie de 25 titres d’un projet de mémoire de master en juin 2025, 23 étaient inventés.

    Même chose pour la #rédaction. Rédiger, ce n’est pas seulement livrer un produit fini, c’est surtout un processus à fonction cognitive qui concrétise la #pensée dans un #discours_organisé, et renvoie à la personne qui écrit son propre #discours à lire, la pousse à s’interroger sur les #termes justes et les #formulations nuancées. Quand on fait produire un texte à une #IAG, cette activité disparaît. On a du mal à identifier quels textes déjà disponibles en ligne l’IAG a pillés, mélangés, vidés de leurs spécificités, et donc à vérifier leur #cohérence et leur #validité. Or l’apprentissage de méthodes à usage autonome, c’est l’objectif majeur d’une formation supérieure. Et quand on utilise une IAG « seulement » pour « améliorer » la forme d’un texte, ce qu’elle sait plutôt bien faire, on court plusieurs #risques qui ne valent pas la #surconsommation_énergétique : perdre en cohérence entre le discours et la pensée qui l’a produit, donner la primauté à la forme sur le fond, uniformiser les modalités d’expression par l’application de #modèles_automatisés... L’une des constatations de l’enquête de 2025, c’est que « l’usage direct et sans encadrement d’une IAG est néfaste sur les apprentissages » (p.24).

    Cela ne signifie pas qu’aucun usage pédagogique pertinent ne puisse être fait d’une IAG, selon les domaines et de manière tutorée, notamment dans les domaines où l’IA fournit une #aide_technique de beaucoup plus haut niveau que ce que faisaient déjà des outils informatiques comme, par exemple, des tableurs ou des visions augmentées (télescopes ou microscopes). Mais, dès lors qu’il s’agit de contenus produits par la #pensée_humaine et utiles pour son développement, de domaines de connaissances où les textes occupent une place importante pour contextualiser dans la complexité du monde et produire prioritairement du #sens, la délégation à une machine crée davantage de manques qu’elle ne viendrait en combler.

    Exemple d’une soutenance de master

    Lors d’une soutenance de Master en Esthétique et Théorie des arts, sur l’insistance du jury, le candidat a admis avoir fait usage de l’IAG pour rédiger son mémoire. Le mémoire de 180 pages était rédigé sans la moindre erreur orthographique. Au niveau formel, rien à redire. Mais l’IAG compile, elle ne pense pas. Elle a en effet combiné des éléments probables d’information sans jamais attiser le désir de les vérifier, en entretenant l’#illusion_de_la_vérité. Elle a conduit à asséner des #généralités dont pas une ne pouvait résister à l’#esprit_critique. Pourtant, il n’y a que sur les pires chaînes de télévision que la compilation d’éléments information est donnée comme équivalente à un #argumentaire bien ficelé.

    Ainsi, pour développer et mettre en travail le concept d’habitus de P. Bourdieu, pourtant l’un des plus travaillés au monde, l’IA a proposé un falot manuel de sociologie pour débutant·es. Lorsque G. Bataille est cité, la référence de l’ouvrage ne comporte pas de numéro de page, l’IAG ne s’embarrassant pas de ces détails. Il fut donc impossible de vérifier s’il parlait effectivement (en 1957) de « ruptures des frontières corporelles dans la danse », ce qui serait très étonnant. L’IAG aura transformé la moindre idée porteuse de sens en #discours_indigent. Avec elle, la pensée propre à l’étudiant et son potentiel à problématiser ont cédé la place à la #banalité.

    Que faudrait-il changer face aux usages risqués de l’IA côté enseignement ? (Voir aussi : UNESCO, 2023, Guide pour l’IA générative dans l’éducation et la recherche : https://unesdoc.unesco.org/ark:/48223/pf0000389901)

    Malgré tout cela, il semble déjà difficile d’empêcher l’usage de l’AI par les étudiant·es.

    Auparavant, on était bien souvent dans une forme de dispositifs d’apprentissage implicites, avec des « raccourcis » grossiers dans la pertinence des évaluations (au risque d’ailleurs d’entraîner l’échec de tous les étudiant·es différent·es de la norme, sans les codes, etc.). La faute à la (non ?) formation à la pédagogie des enseignant·es du supérieur, mais aussi au manque de moyens. Également au déficit, dans l’évaluation de la carrière des E-C, de reconnaissance de l’expertise en enseignement, face à l’importance accordée aux activités de recherche.

    Si on veut garder un niveau d’apprentissage sérieux, relatif à ce qui peut s’ancrer durablement dans l’esprit de nos étudiant·es, on est donc face à la nécessité d’adapter nos #méthodes_pédagogiques. Le remède n’est pas forcément inaccessible. On doit s’assurer en détail que les étudiant·es travaillent pour de bon l’élaboration progressive d’une maîtrise des diverses #compétences et de leur articulation. On est donc forcés de faire une mesure plus fine de l’authenticité, des progressions dans le temps, plutôt que la simple #évaluation d’un résultat final. Tout cela va avoir un coût humain et logistique : organiser par exemple beaucoup plus de soutenances à l’oral, en présentiel et synchrone. Et devoir préciser et vérifier à chaque étape si l’IAG est acceptée ou non. Et si oui comment elle est utilisée...

    Il faudrait en somme mieux appliquer les pratiques adéquates standards de la pédagogie, comme l’alignement des dispositifs d’évaluation, par exemple. Tout cela requiert beaucoup d’efforts de la part des enseignant·es, et de moyens, des formations, un taux d’encadrement nettement plus massif. Il faut remettre plus d’humain dans la boucle. Hélas, ce n’est pas la tendance politique du moment. L’IAG porte la promesse magique de la #productivité — et il n’y a pas ou que peu d’alternatives puisque le marché en fourgue partout dans nos appareils et nos logiciels. Pourtant, si on veut former à l’#effort dans un monde de facilité, ça va coûter plus cher.

    https://cgt.fercsup.net/l-echo-du-sup/echo-du-sup-numero-11-juin-2026-l-ia-dans-l-esr-ou-l-esr-dans-l-ia/article/l-ia-dans-les-formations-superieures-beaucoup-d-effets-deleteres-et-peu
    #IA #AI #intelligence_artificielle #ESR #enseignement_supérieur #université #facs #pédagogie #à_lire

    • L’IA générative bouleverse-t-elle les pratiques pédagogiques ?

      En bref

      – Rendu public par OpenAI en 2023, GPT-4 a atteint des niveaux de performance comparables à ceux d’étudiants de second cycle sur des exercices de logique, de mathématiques et de rédaction académique.
      – Les #modèles_de_langage modifient la manière dont les étudiants mobilisent leur raisonnement et leur capacité analytique, ce qui peut mener à une fragilisation de leur plasticité cérébrale et de leur densification des réseaux neuronaux.
      – Lorsque assisté par l’IA, l’acquisition des connaissances peut être affaiblie dès qu’elle remplace systématiquement l’#effort_intellectuel : les productions écrites, le #travail_autonome et les modalités d’évaluation.
      – De nombreuses questions sur l’équilibre entre assistance algorithmique et #effort_cognitif humain sont soulevées, d’autant par la rapide évolution des modèles d’IA.
      – Des cadres commencent à émerger où l’IA n’est ni absente ni centrale, mais intégrée de manière différenciée selon les objectifs cognitifs poursuivis.

      **

      L’irruption de l’intelligence artificielle générative dans les systèmes éducatifs marque un tournant technologique. Contrairement aux plateformes d’apprentissage en ligne ou aux outils d’assistance pédagogique des années 2000 et 2010, les modèles de langage de grande taille produisent désormais des raisonnements structurés, synthétisent des corpus complexes et interagissent avec les apprenants de manière adaptative.

      GPT‑4, rendu public par OpenAI en 2023, a atteint des niveaux de performance comparables à ceux d’étudiants de second cycle sur des exercices de logique, de mathématiques et de rédaction académique1. D’autres architectures comme Claude d’Anthropic ou LLaMA de Meta confirment cette dynamique tout en explorant des stratégies de gouvernance des sorties génératives et de réduction des biais2.

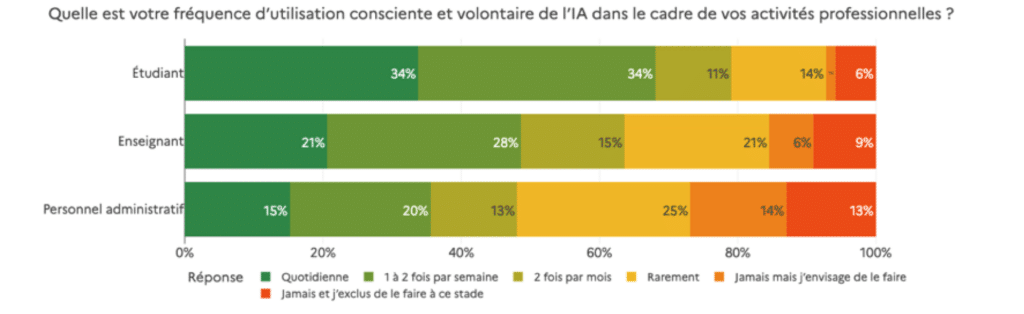
      Ces avancées offrent de nouvelles opportunités pour personnaliser les parcours, renforcer le tutorat individualisé et élargir l’accès aux ressources pédagogiques. Elles soulèvent toutefois des interrogations sur les fréquences d’utilisations (voir figure 1) et les conditions cognitives de l’apprentissage assisté par IA, car certaines dimensions de l’acquisition des connaissances peuvent être fragilisées lorsque cette technologie remplace systématiquement l’effort intellectuel3.

      Ces enjeux touchent directement des dispositifs clés de l’enseignement supérieur, tels que la production écrite, le travail autonome et les modalités d’évaluation. De plus, ces transformations appellent une approche combinant recherche académique et observation des pratiques pédagogiques.
      L’effort cognitif à l’épreuve des modèles génératifs

      Les modèles de langage de grande taille modifient la manière dont les étudiants mobilisent leur raisonnement et leur capacité analytique. GPT‑4, par exemple, atteint des performances comparables à celles d’étudiants de second cycle sur des exercices de logique, de mathématiques et de synthèse textuelle5. Cette portée soulève des questions sur l’équilibre entre assistance algorithmique et effort cognitif humain.

      « Le problème, dans le champ éducatif, apparaît lorsque l’étudiant utilise systématiquement l’IA pour réaliser un exposé, un mémoire, une dissertation ou même pour apprendre une notion » affirme Michel Barabel, maître de conférences à l’Université Paris-Est dont les travaux portent sur la transformation des organisations, en particulier la gestion des compétences, la formation professionnelle et les cultures apprenantes. La sous-traitance systématique peut nuire au développement de capacités cognitives essentielles. « Les travaux de recherche montrent que dans ce cas, le coût de l’effort cognitif augmente rapidement et que faire seul devient de plus en plus difficile ».

      Les cadres théoriques de la psychologie cognitive permettent d’éclairer ce phénomène. Les distinctions de Daniel Kahneman entre le cerveau de type 1, analytique et paresseux, et le cerveau de type 2, créatif et mobilisé dans la résolution de situations inédites, servent de référence. Barabel observe que « la grande promesse de l’IA est précisément de sous-traiter les tâches relevant du cerveau de type 1, simples et répétitives, afin de libérer du temps pour des activités de type 2 ». Son usage répété dans des tâches fondamentales du type 1 peut ainsi limiter la densification des réseaux neuronaux nécessaires à la créativité et à la pensée critique.

      Une comparaison avec d’autres usages technologiques illustre ce risque. « Cette dépendance pose une question centrale, celle d’un appauvrissement progressif des capacités cognitives », explique Barabel, faisant référence à des exemples observés dans d’autres contextes, comme la navigation des chauffeurs de taxi londoniens devenue dépendante du GPS. Les travaux en neurosciences montrent que l’apprentissage reposant sur un engagement cognitif actif favorise la plasticité cérébrale et la densification des réseaux neuronaux, tandis qu’une réduction durable de l’effort analytique limite ces mécanismes et fragilise la mobilisation des compétences dans des situations complexes6. « Or, on sait qu’il est très difficile de faire émerger une créativité authentique sans ce socle d’effort cognitif préalable », ajoute l’expert.

      Cette réflexion sur l’effort cognitif souligne que les effets de l’IA générative dépendent moins de la technologie que des modalités d’usage. L’usage réfléchi et régulé peut soutenir la créativité et la productivité, tandis qu’un usage passif peut compromettre le développement de compétences intellectuelles essentielles.
      Des recours pédagogiques en recomposition progressive

      La diffusion rapide des outils d’IA générative a rendu visibles des usages déjà largement installés chez les étudiants, souvent en dehors de tout cadre institutionnel. Plusieurs travaux montrent que ces outils sont mobilisés pour rédiger des exposés, structurer des mémoires ou préparer des évaluations, sans que les dispositifs pédagogiques aient été conçus pour en tenir compte7. Cette situation a conduit certains établissements à repenser non pas seulement la régulation, mais la nature même des activités proposées.

      D’après Michel Barabel, « la question ne peut se réduire à une opposition entre autorisation et interdiction. Le problème ne doit pas être posé en ces termes ». Il stipule que l’IA combine des potentialités pédagogiques fortes et des limites réelles. Dans les dispositifs qu’il observe, l’enjeu consiste à distinguer plusieurs formes d’activités selon le rôle attribué à la machine. « Certaines activités peuvent être totalement confiées à l’IA sans régulation particulière », notamment lorsqu’il s’agit de procédures ou d’aide méthodologique, tandis que d’autres doivent rester exclusivement humaines. « L’usage de l’IA y est interdit afin de préserver la relation pédagogique, le travail du cerveau de type 1 et la créativité et l’esprit critique ».

      Cette différenciation se traduit concrètement par des dispositifs de transparence. « À Sciences Po et à l’IAE Paris-Est, les étudiants doivent expliciter leur usage de l’IA dans une annexe dédiée. Nous autorisons son exploitation, mais nous imposons une annexe IA dans tous les travaux », précise Barabel. Cette exigence permet de déplacer l’évaluation du seul résultat vers le processus intellectuel mobilisé. « Le nouveau plagiat, pour nous, n’est pas d’utiliser l’IA, mais de l’utiliser sans le déclarer », ajoute-t-il.

      Les modalités d’évaluation ont également été ajustées pour tenir compte de ces pratiques. Barabel observe qu’« un exposé à rendre pour la semaine suivante a aujourd’hui une probabilité très élevée d’être produit à 60, 70, voire 90 % à l’aide de l’IA ». Dans ce contexte, « là où l’écrit pesait auparavant davantage, l’oral est désormais majoritaire », afin de vérifier la compréhension, l’appropriation des concepts et la faculté de l’étudiant à défendre son raisonnement.

      Entre délégation, assistance et augmentation, les applications pédagogiques se structurent ainsi autour d’un principe d’articulation. « Il existe des situations où l’IA assiste l’étudiant », note Barabel, tandis que dans d’autres configurations, « l’étudiant produit une première version et l’IA l’aide à l’améliorer par questionnement et suggestions ». Ces expérimentations dessinent progressivement un cadre où cette technologie n’est ni absente ni centrale, mais intégrée de manière différenciée selon les objectifs cognitifs poursuivis.
      Entre promesses d’augmentation et risques de fragmentation

      Les limites actuelles de l’IA générative en contexte éducatif tiennent moins à ses performances techniques qu’aux effets systémiques qu’elle induit sur les trajectoires d’apprentissage. Les bénéfices cognitifs observés dépendent fortement des conditions d’emploi, avec des résultats parfois contradictoires selon les protocoles expérimentaux[8]. Michel Barabel invite ainsi à la prudence dans l’interprétation des premières données disponibles. « Certaines études, notamment du MIT, ont montré une baisse rapide de certaines capacités cognitives, mais sur des échantillons très réduits et avec des protocoles discutables », rappelle-t-il, tout en notant que d’autres travaux mettent en évidence des effets positifs sur certaines compétences.

      Cette hétérogénéité des résultats renvoie à une question centrale, celle de l’intensité et surtout de la nature des utilisations. « Il pas certain qu’il existe un seuil universel », précise Barabel, en soulignant que « le problème réside davantage dans l’organisation des activités que dans le volume d’interaction avec l’IA ». Il propose un équilibre théorique dans lequel « le 100 % humain devrait représenter au moins 20 % des activités », afin de préserver les fonctions cognitives fondamentales liées à l’effort, à la réflexion autonome et à la construction du jugement.

      Au-delà des effets individuels, les chercheurs s’inquiètent de dynamiques d’inégalités susceptibles d’être amplifiées par les systèmes intelligents. Les écarts d’accès aux versions les plus performantes des modèles, souvent conditionnés par des abonnements payants, constituent un premier facteur de différenciation[9]. Barabel met en évidence le fait que « le capital économique des familles pourrait conditionner l’accès à des IA plus performantes, utilisées dans un cadre privé », créant un avantage cumulatif pour certains étudiants. À cela s’ajoutent les disparités institutionnelles. « Certains établissements disposent des moyens financiers et pédagogiques pour déployer des IA, former les enseignants et mettre en place des chartes éthiques. D’autres non ».

      Ces écarts matériels se doublent d’inégalités culturelles et cognitives. « Le risque majeur est alors l’accroissement des écarts entre étudiants », pointe Barabel, distinguant ceux qui utilisent l’IA de manière stratégique, ceux qui en font un usage mécanique et ceux qui réinvestissent le temps libéré dans des activités à forte valeur cognitive. Les recherches en sociologie de l’éducation montrent que ces mécanismes d’appropriation différenciée jouent un rôle déterminant dans la reproduction ou la transformation des hiérarchies scolaires8.

      Enfin, la rapidité d’évolution des technologies pose un défi structurel aux institutions éducatives. « Ce que nous disons aujourd’hui peut être remis en cause dans quelques mois par une nouvelle génération d’IA », signale Barabel. Cette instabilité technologique interroge la capacité des systèmes éducatifs à articuler innovation, équité et développement des compétences humaines fondamentales, dans un contexte où la production et la transmission des savoirs sont elles-mêmes en profonde recomposition.

      https://www.polytechnique-insights.com/tribunes/digital/lia-generative-bouleverse-t-elle-les-pratiques-pedagogiques

    • Le plus grand danger de l’IA à l’université n’est pas la triche, c’est l’érosion de l’apprentissage lui‑même

      L’intelligence artificielle promet de « libérer du temps » et d’optimiser l’apprentissage. Mais en déléguant aux machines les tâches qui formaient étudiants et jeunes chercheurs, les universités risquent d’éroder les conditions mêmes de l’expertise.

      Dans le débat public sur l’intelligence artificielle (IA) à l’université, une inquiétude revient en boucle : la tricherie. Les étudiants vont-ils confier leurs #dissertations à des #chatbots ? Les enseignants sauront-ils les démasquer ? Faut-il interdire ces outils sur les campus, ou au contraire les intégrer aux pratiques pédagogiques ?

      Ces questions sont légitimes. Mais à force de réduire le sujet à la #fraude_académique, on passe à côté de l’essentiel : une transformation beaucoup plus profonde est déjà à l’œuvre, qui dépasse largement les seuls comportements des étudiants – et même le cadre de la salle de classe.

      Les universités déploient désormais l’IA dans de nombreux aspects de leur fonctionnement. Certaines applications restent largement invisibles : des systèmes qui aident à répartir les ressources, à repérer les étudiants « à risque », à optimiser les emplois du temps ou à automatiser des décisions administratives routinières.

      D’autres usages sont, eux, beaucoup plus visibles. Les étudiants s’appuient sur des outils d’IA pour résumer des cours et réviser. Les enseignants les utilisent pour élaborer des sujets d’évaluation, préparer des syllabus. Les chercheurs s’en servent pour écrire du code, passer en revue la littérature scientifique ou condenser en quelques minutes des tâches fastidieuses qui prenaient auparavant des heures.

      On peut bien sûr utiliser l’IA pour tricher ou se soustraire à un devoir. Mais la multiplication de ses usages dans l’enseignement supérieur – et les bouleversements qu’ils annoncent – posent une question bien plus fondamentale : à mesure que les machines deviennent capables d’assumer une part croissante du travail de recherche et d’apprentissage, que devient l’université ? À quoi sert-elle encore ?

      Depuis huit ans, nous étudions les implications morales d’un recours massif à l’IA dans le cadre d’un projet de recherche conjoint entre le Applied Ethics Center at UMass Boston et l’Institute for Ethics and Emerging Technologies. Dans un livre blanc récent, nous soutenons qu’à mesure que les systèmes d’IA gagnent en autonomie, les enjeux éthiques de leur utilisation dans l’enseignement supérieur s’intensifient – tout comme les conséquences potentielles qui en découlent.

      À mesure que ces technologies deviennent plus performantes dans la production de travaux intellectuels – concevoir des cours, rédiger des articles, proposer des protocoles expérimentaux ou résumer des textes complexes – elles ne se contentent pas d’accroître la productivité des universités. Elles risquent aussi de vider de sa substance l’écosystème d’apprentissage et de mentorat sur lequel ces institutions sont fondées – et dont elles dépendent pour exister.
      IA non autonomes

      On peut distinguer trois types de systèmes d’IA et leurs effets respectifs sur la vie universitaire.

      Des logiciels alimentés par l’IA sont déjà utilisés dans l’enseignement supérieur pour l’examen des candidatures, les achats, l’accompagnement pédagogique des étudiants ou encore l’évaluation des risques institutionnels.

      On parle ici de systèmes « non autonomes » : ils automatisent certaines tâches, mais un humain reste « dans la boucle » et les utilise comme de simples outils.

      Ces technologies peuvent faire peser un risque sur la vie privée et la sécurité des données des étudiants. Elles peuvent aussi être biaisées. Et elles manquent souvent de transparence, ce qui rend difficile l’identification de l’origine de ces problèmes. Qui a accès aux données ? Comment sont calculés les « indices prédictifs de décrochage ou d’échec » ? Comment éviter que ces systèmes ne reproduisent des inégalités ou ne traitent certains étudiants comme de simples cas problématiques à gérer ?

      Ces questions sont sérieuses. Mais, au moins dans le champ de l’informatique, elles ne sont pas fondamentalement nouvelles. Les universités disposent en général de services de conformité, de comités d’éthique de la recherche et de mécanismes de gouvernance pensés pour anticiper ou limiter ces risques – même si, dans les faits, ils n’atteignent pas toujours pleinement ces objectifs.
      IA hybrides

      Les systèmes hybrides regroupent toute une gamme d’outils, parmi lesquels des bots conversationnels assistés par l’IA, des dispositifs de feedback personnalisé ou encore des aides automatisées à l’écriture. Ils reposent souvent sur des technologies d’IA générative, notamment sur de grands modèles de langage, les LLM. Si les utilisateurs humains fixent les objectifs généraux, les étapes intermédiaires que le système mobilise pour les atteindre ne sont, elles, généralement pas spécifiées.

      Ces systèmes hybrides façonnent de plus en plus le travail académique au quotidien. Les étudiants les utilisent comme compagnons d’écriture, tuteurs, partenaires de réflexion ou outils d’explication à la demande. Les enseignants s’en servent pour élaborer des grilles d’évaluation, préparer des cours ou concevoir des plans de syllabus. Les chercheurs les mobilisent pour résumer des articles, commenter des versions préliminaires, imaginer des protocoles expérimentaux ou générer du code.

      C’est ici que le débat sur la « tricherie » trouve véritablement sa place. Alors qu’étudiants et enseignants s’appuient de plus en plus sur ces outils pour se faire aider, il est légitime de s’interroger sur les formes d’apprentissage qui risquent de se perdre en chemin. Mais les systèmes hybrides soulèvent aussi des questions éthiques plus complexes.

      L’une d’elles concerne la transparence. Les chatbots d’IA proposent des interfaces en langage naturel qui rendent difficile de savoir si l’on échange avec un humain ou avec un agent automatisé. Cette ambiguïté peut être déstabilisante et source de distraction. Un étudiant qui révise pour un examen doit pouvoir savoir s’il s’adresse à son chargé de travaux dirigés ou à un robot. De même, un étudiant qui lit les commentaires sur son mémoire doit pouvoir identifier clairement s’ils proviennent de son enseignant.

      Tout manque de transparence dans ces situations risque d’aliéner les personnes concernées et de déplacer l’attention des interactions académiques : au lieu de se concentrer sur l’apprentissage, on se focalise sur les outils ou la technologie qui le médiatisent. Des chercheurs de l’Université de Pittsburgh ont montré que ces dynamiques suscitent chez les étudiants des sentiments d’incertitude, d’anxiété et de méfiance. Des effets loin d’être anodins.

      Une deuxième question éthique touche à la responsabilité et au crédit intellectuel. Si un enseignant utilise l’IA pour rédiger un sujet et qu’un étudiant s’appuie lui aussi sur l’IA pour produire sa réponse, qui évalue qui – et qu’est-ce qui est réellement évalué ? Si les retours sont en partie générés par une machine, qui est responsable lorsqu’ils induisent en erreur, découragent ou intègrent des présupposés invisibles ? Et lorsque l’IA contribue de manière substantielle à une synthèse de recherche ou à la rédaction d’un article, les universités devront établir des normes plus claires en matière d’autorat et de responsabilité – pas seulement pour les étudiants, mais aussi pour les enseignants-chercheurs.

      Enfin se pose la question cruciale de la « décharge cognitive ». L’IA peut réduire les tâches fastidieuses, et cela n’a rien de problématique en soi. Mais elle peut aussi détourner les utilisateurs des étapes de l’apprentissage qui construisent réellement les compétences : formuler des idées, traverser des moments de confusion, retravailler un brouillon maladroit, apprendre à repérer ses propres erreurs.
      Agents autonomes

      Les transformations les plus profondes pourraient venir de systèmes qui ressemblent moins à des assistants qu’à de véritables agents. Si les technologies pleinement autonomes relèvent encore en partie de l’aspiration, l’idée d’un « chercheur en boîte » – un système d’IA agentique capable de mener des études de manière indépendante – devient de plus en plus crédible.

      Ces outils dits agentiques sont présentés comme susceptibles de « libérer du temps » pour des activités mobilisant davantage des capacités humaines, comme l’empathie ou la résolution de problèmes. Dans l’enseignement, cela pourrait signifier que les enseignants continuent d’assurer les cours au sens formel, mais que la majeure partie du travail pédagogique quotidien soit déléguée à des systèmes optimisés pour l’efficacité et le passage à l’échelle. En recherche, l’avenir semble appartenir aux systèmes capables d’automatiser toujours davantage le cycle scientifique. Dans certains domaines, cela prend déjà la forme de laboratoires robotisés fonctionnant en continu, capables d’automatiser une grande partie des expérimentations et même de sélectionner de nouveaux tests à partir des résultats précédents.

      À première vue, cela peut sembler être un gain intéressant de productivité. Mais les universités ne sont pas des usines à produire de l’information : ce sont des communautés de pratique. Elles reposent sur un vivier de doctorants et de jeunes chercheurs qui apprennent à enseigner et à faire de la recherche en participant eux-mêmes à ces activités. Si des agents autonomes absorbent une part croissante des tâches « routinières » qui constituaient historiquement des portes d’entrée dans la carrière académique, l’université pourra continuer à produire des cours et des publications – tout en fragilisant silencieusement les structures d’apprentissage qui permettent, dans la durée, de former l’expertise.

      La même dynamique touche les étudiants de premier cycle, sous une forme différente. Lorsque des systèmes d’IA peuvent fournir à la demande des explications, des brouillons, des solutions ou des plans de révision, la tentation est grande de déléguer les aspects les plus exigeants de l’apprentissage. Pour l’industrie qui promeut l’IA dans les universités, ce type d’effort peut apparaître comme « inefficace » – et l’on pourrait penser que les étudiants gagneraient à laisser la machine s’en charger. Mais c’est précisément dans cette confrontation à la difficulté que se construit une compréhension durable. La psychologie cognitive a montré que les étudiants progressent intellectuellement en rédigeant, en révisant, en échouant, en recommençant, en affrontant la confusion et en retravaillant des arguments faibles. C’est cela, apprendre à apprendre.

      Pris ensemble, ces évolutions suggèrent que le principal risque lié à l’automatisation dans l’enseignement supérieur ne réside pas seulement dans le remplacement de certaines tâches par des machines, mais dans l’érosion plus profonde de l’écosystème de pratiques qui, depuis longtemps, soutient l’enseignement, la recherche et l’apprentissage.
      Un tournant risqué

      À quoi servent les universités dans un monde où le travail intellectuel est de plus en plus automatisé ?

      Une première réponse consiste à voir l’université avant tout comme une machine à produire des diplômes et des connaissances. Dans cette logique, la question centrale devient celle des résultats : les étudiants obtiennent-ils leurs diplômes ? Des articles sont-ils produits ? Fait-on des découvertes ? Si des systèmes autonomes peuvent générer ces résultats plus efficacement, alors l’institution a toutes les raisons de les adopter.

      Mais une autre réponse considère l’université comme bien davantage qu’une simple machine à produire des résultats. Elle reconnaît que la valeur de l’enseignement supérieur réside en partie dans l’écosystème lui-même : le continuum d’opportunités grâce auquel les novices deviennent experts, les structures de mentorat au sein desquelles se forment le jugement et le sens des responsabilités, et une conception pédagogique qui valorise l’effort et la confrontation à la difficulté plutôt que leur élimination au nom de l’efficacité.

      Dans cette perspective, l’enjeu n’est pas seulement de savoir si des connaissances et des diplômes sont produits, mais comment ils le sont – et quels types de personnes, de compétences et de communautés se construisent au passage. L’université y apparaît comme un écosystème dont la mission est, ni plus ni moins, de former durablement l’expertise et le discernement humains.

      Dans un monde où le travail intellectuel est lui-même de plus en plus automatisé, les universités doivent, selon nous, s’interroger sur ce qu’elles doivent à leurs étudiants, à leurs jeunes chercheurs et à la société qu’elles servent. Les réponses à ces questions détermineront non seulement la manière dont l’IA sera intégrée, mais aussi ce que deviendra l’université contemporaine.

      https://theconversation.com/le-plus-grand-danger-de-lia-a-luniversite-nest-pas-la-triche-cest-l
      #tricherie

  • AnarBib — Réseau de bibliothèques libertaires
    https://anarbib.org/fr
    Cataloguer un fonds, suivre les emprunts, accueillir des lecteur·rices, coopérer avec d’autres bibliothèques du mouvement : ce sont des gestes simples, qu’aucun outil existant ne respecte vraiment.

    Les logiciels propriétaires sont chers, surveillent leurs utilisateur·rices et imposent leurs catégories. Les outils libres généralistes sont conçus pour des bibliothèques universitaires ou municipales, pas pour les nôtres.

    AnarBib fait autrement : un outil pensé depuis nos pratiques, pour nos fonds, dans nos langues.

    #anarbib #bibliotheque #gestion #

  • Le Bateau-usine et les entrepôts Amazon, 1929-2026
    https://tagrawlaineqqiqi.wordpress.com/2026/08/13/le-bateau-usine-et-les-entrepots-amazon-1929-2026

    Je n’étais pas sortie aussi physiquement épuisée par une lecture depuis La Scierie, chef d’œuvre anonyme de la littérature du travail qui fait transpirer et donne des courbatures, mais dans Le Bateau-usine, en plus du travail incroyablement difficile, il faut encore ajouter les maltraitances physiques du capitalisme qui flirte avec l’esclavagisme. Le Bateau-Usine de Kobayashi […]

    #Bibliothèque #Société
    https://0.gravatar.com/avatar/cd5bf583a4f6b14e8793f123f6473b33bb560651f18847079e51b3bcad719755?s=96&d=

  • Restituite la biblioteca ai ragazzi di #caserta!
    https://informareonline.com/restituite-la-biblioteca-ai-ragazzi-di-caserta

    A quasi due anni dal nostro primo #Reportage, siamo tornati per verificare lo stato del luogo Finalmente il cartello di cantiere e la speranza che questa volta i #lavori arrivino davvero fino in fondo. Sì, perché per la comunità studentesca casertana la Biblioteca Comunale “Alfonso Ruggiero”, in via Laviano, non è mai stata soltanto un […] L’articolo Restituite la biblioteca ai ragazzi di Caserta! proviene da Informareonline, scritto da Gianrenzo Orbassano

    #Approfondimenti #Attualità #EVIDENZA #Magazine_Agosto_2026 #biblioteca_comunale_alfonso_ruggiero

  • La Soif, d’Andreï Guelassimov
    https://tagrawlaineqqiqi.wordpress.com/2026/07/23/la-soif-dandrei-guelassimov

    « Oh ben ça alors ! « , m’exclamai-je en refermant ce court roman qui ne va pas du tout là où on aurait pu s’y attendre. C’est que l’histoire démarrait tout à fait tragiquement : un jeune homme qui a eu le visage entièrement brûlé alors qu’il était soldat appelé en Tchétchénie vient de terminer un […]

    #Bibliothèque #lecture #Russie
    https://0.gravatar.com/avatar/cd5bf583a4f6b14e8793f123f6473b33bb560651f18847079e51b3bcad719755?s=96&d=

  • Schock im Maison de France : Wütender Besucher löst fast ein Inferno aus
    https://www.berliner-kurier.de/berlin/angriff-auf-buecher-im-maison-de-france-li.10151051

    Il n’est pas d’accord avec ce qu’il lit dans livre, il met le feu à la bibliothèque française de Berlin. Les dégats ne sont pas importants mais l’événement rappelle quand même l’attentat dcontre la Maison de France de 1983.

    30.6.2026 von Tanja Tal - Im Maison de France löste ein 35-Jähriger ein schweres Feuer aus. Mit Benzin attackierte er eine Bibliothek. Ein mutiger Besucher verhinderte eine Katastrophe.

    Schrecksekunden im Kulturzentrum Maison de France: Statt in der Bibliothek zu lesen, ging ein Besucher wütend mit Benzin gegen Bücher vor.

    Besucher verhindert mit einem Feuerlöscher Schlimmeres

    Was trieb Abdoul R. (35), den Feuerteufel, an? Neun Monate später begann der Prozess gegen einen Mann, der beinahe einen Großbrand verursacht hätte. Der Ankläger: „Bücher und Holzregale – alles hätte wie Zunder brennen können. Zum Glück hat ein Besucher geistesgegenwärtig zum Feuerlöscher gegriffen, die Flammen gelöscht.“

    Angeklagter liebt das Lesen und die Kultur

    R. kleinlaut vor der Richterin. Ein Oberleitungsmonteur aus Weißenfels (Sachsen-Anhalt). Er war am 20. September 2025 als Besucher in Berlin: „Ich wollte Urlaub machen.“ Mit viel Kultur. „Ich bin ein Mensch, der gerne liest und Bücher liebt.“

    Foto
    Der Gesamtschaden im Maison de France wird mit 6530 Euro angegeben.imago/Jürgen Ritter

    Es zog ihn in die Abteilung Geschichte. R.: „Ich las in drei Büchern.“ Ein spezielles Thema interessierte den Mann, der aus Burkina Faso (Westafrika) stammt: „Ich habe über Sklavenzeit gelesen und was mit den Menschen passiert ist.“
    Geschichte wühlt den Angeklagten auf

    Es habe ihn wütend gemacht: „Ich fand, die Geschichte war in den Büchern schlecht oder sogar falsch erzählt.“ Das habe ihm keine Ruhe gelassen: „Am nächsten Tag bin ich wieder hin, wollte etwas machen.“

    Es war ein großer Fehler. Dafür habe ich zu bezahlen. Stück für Stück werde ich alles abzahlen. Abdoul R., Angeklagter

    Die Richterin: „Es sollen etwa 25 Besucher in der Bibliothek gewesen sein. Haben Sie daran gedacht, dass Leute in Gefahr waren?“ Abdoul R. nickte: „Ich wollte den Menschen nichts tun und sagte noch, dass sie besser rausgehen sollten.“
    Sachschaden beläuft sich auf 6530 Euro

    Er hatte Benzin gekauft und außerdem Bremsenreiniger in der Tasche. Die Anklage: „Er verschüttete die Mittel über Bücher in zwei Regalen, zündete dann mit dem Feuerzeug an.“ An drei Stellen brannte es.

    Eine Mitarbeiterin der Bibliothek im Institut français am Kurfürstendamm: „200 Bücher haben wir verloren.“ Zerstört durch Flammen oder durch Löschwasser. Sachschaden insgesamt: 6.530 Euro.
    Polizei fasst den Täter vor Ort

    Die Polizei fasste R. noch vor Ort. Mit schwerem Gepäck durfte er zurück nach Weißenfels reisen: Anzeige wegen versuchter schwerer Brandstiftung und Sachbeschädigung.

    Das Kulturzentrum Maison de France war im April 1950 als deutsch-französische Begegnungsstätte eröffnet worden. Die Richterin zum Angeklagten: „Alle, die im Haus waren, hatten unfassbares Glück! So ein Feuer kann sich rasant ausbreiten.“
    Täter will für seine Tat geradestehen

    Planvoll sei R. vorgegangen. Auch der Verteidiger: „Wenn man Bücher nicht lesen möchte, dann muss man es nicht tun. Aber andere davon abzuhalten, das geht nicht.“ R. einsichtig: „Es war ein großer Fehler. Dafür habe ich zu bezahlen. Stück für Stück werde ich alles abzahlen.“ Urteil: Ein Jahr Haft auf Bewährung.

    Bombenanschlag 1983
    https://de.wikipedia.org/wiki/Maison_de_France

    Am 25. August 1983 wurde ein Bombenanschlag auf das Haus verübt, bei dem der Radsportler Michael Haritz starb, der gerade mit seiner Friedensgruppe „Fasten für das Leben“ im französischen Generalkonsulat eine Petition übergeben wollte. Weitere 23 Personen wurden verletzt. Die Bombe wurde von dem Libanesen Mustafa Ahmed el-Sibai gelegt, der im Auftrag der armenischen Terrorgruppe „Asala“ handelte.[12] Geplant wurde der Anschlag von dem Attentäter Johannes Weinrich, der dafür im Jahr 2000 in Berlin zu einer lebenslangen Haftstrafe verurteilt wurde.[13] Weinrich galt als die rechte Hand des Terroristen Carlos, der mit dem Attentat auch seine Freundin Magdalena Kopp freipressen wollte.[14] Wie sich später herausstellte, wurde das Attentat mit Unterstützung des Ministeriums für Staatssicherheit (MfS) durchgeführt. Der ehemalige Oberstleutnant des MfS Helmut Voigt wurde hierfür 1994 in einem Prozess vor dem Landgericht Berlin[15] zu vier Jahren Freiheitsstrafe wegen Beihilfe zum Mord verurteilt.

    #Berlin #Charlottenburg #Kurfürstendamm #fait_divers #bibliothèque #culture #incendie

  • Giugliano, grande attesa per la presentazione della #Fondazione_Giovan_Battista_Basile presso la #biblioteca_comunale
    https://informareonline.com/giugliano-grande-attesa-per-la-presentazione-della-fondazione-giova

    Un’iniziativa unica, volta a celebrare e rendere omaggio all’inventore del genere fiabesco, noto in tutto il mondo per aver creato il mito di Cenerentola tra i più noti: Giovan Battista Basile. Ed è proprio per rendere ormaggio alla sua figura – nonché alla Fondazione che porta il suo nome, istituita a #Giugliano_in_Campania – […] L’articolo Giugliano, grande attesa per la presentazione della Fondazione Giovan Battista Basile presso la Biblioteca Comunale proviene da Informareonline, scritto da Redazione Informare

    #Comunicati_Stampa #Emanuele_Coppola

  • Une bibliothèque nationale glisse ses archives dans une fiole d’ADN
    https://actualitte.com/article/131740/insolite/une-bibliotheque-nationale-glisse-ses-archives-dans-une-fiole-d-adn

    La Library of Congress déposera dans l’America250 Time Capsule une fiole d’ADN synthétique contenant des copies numériques de trésors patrimoniaux. Le brouillon de Jefferson, des manuscrits, sons et archives passeront dans une mémoire moléculaire programmée pour 2276, à Philadelphie. Une expérience minuscule par son format, immense par les questions qu’elle adressera aux futurs lecteurs.

    Il y aurait plein de choses à dire sur cette expérience... mais un non-dit qui me semble à la fois curieux et inquiétant : si on transfère la mémoire pour seulement 250 ans dans un matériaux qui n’est ni sensible aux changements climatiques, à des impulsions électromagnétiques (genre bombe atomique), à des destructions volontaires ou involontaires ou à des incendies, des inondations... c’est peut être que l’on s’inquiète de l’avenir du monde civilisé actuel, qu’on redoute les guerres et les bouleversements climatiques. Mais dans ce cas, préserver est-il le plus urgent ? Agir contre les forces de la destructivité est certainement plus efficace. Enfin, j’espère...

    #Bibliothèque #Archives #ADN #Mémoire

  • #Aversa, nuovo raid alla #Casa_della_Cultura
    https://informareonline.com/aversa-nuovo-raid-alla-casa-della-cultura

    Distrutta la Casa della Cultura ad Aversa. È l’ennesimo raid vandalico avvenuto nella struttura “Vincenzo Caianello” di via Tristano, ad Aversa, all’interno dell’ex macello comunale. A essere colpita, ancora una volta, è stata la #biblioteca_del_Museo_di_Storia_Militare, già finita nei progetti dei vandali lo scorso gennaio. Questa volta però i danni sono […] L’articolo Aversa, nuovo raid alla Casa della Cultura proviene da Informareonline, scritto da Manuel Vita Verde

    #Approfondimenti #Attualità #la_politica_che_serve

  • Britannica pillé par ChatGPT : comment Umberto Eco avait prévu ce vertige
    https://actualitte.com/article/131308/enquetes/britannica-pille-par-chatgpt-comment-umberto-eco-avait-prevu-ce-vertige

    Les plaignants soutiennent que les produits fondés sur ChatGPT profitent de ces contenus de référence tout en captant les lecteurs par des synthèses qui se substituent aux visites sur leurs sites. Le grief économique rejoint donc une question intellectuelle : qui rend le savoir vérifiable lorsque l’interface coupe le trajet vers la source ?

    Une encyclopédie ne vaut pas seulement par ses articles, mais par la possibilité de revenir à ceux qui les écrivent, les vérifient, les signent et les révisent. Pour les métiers du livre, la conséquence est concrète : aucune synthèse automatique ne remplace une source identifiable, consultable et responsable.

    #Umberto_Eco #Bibliothèque #Connaissance #Sources_documentaires

  • Hallucinated citations are polluting the scientific literature. What can be done?

    Tens of thousands of publications from 2025 might include invalid references generated by AI, a Nature analysis suggests.

    Earlier this year, computer scientist Guillaume Cabanac received a notification from Google Scholar that one of his publications had been cited in a paper published in the International Dental Journal1. That was unexpected, because his research on spotting fabricated papers doesn’t typically intersect with dentistry. “I was very surprised to see that I couldn’t recognize my own reference,” says Cabanac, who is based at the University of Toulouse in France.

    The title in the citation resembled that of a preprint2 he had posted in 2021 and never published formally, but the journal was listed as Nature and the DOI — the unique identifier assigned by publishers and preprint repositories — did not lead to the original preprint. “I got very concerned,” adds Cabanac, who immediately suspected that the citation had been hallucinated by artificial intelligence.

    This is just one example of a rapidly growing problem. Surveys and related studies have shown that researchers are increasingly using large language models (LLMs) to help to conduct literature searches, write manuscripts and format bibliographies. And sometimes, these models generate non-existent academic references.

    Over the past year, efforts have begun turning up such hallucinated citations in the literature. One analysis of nearly 18,000 papers accepted by three computer-science conferences found a sharp increase in references that cannot be traced to actual scholarly publications3. The results, reported in January, indicated that 2.6% of papers in 2025 had a least one potentially hallucinated citation — up from about 0.3% in 2024. Another analysis, released in February, estimated that 2–6% of papers in four other 2025 computer-science conferences included references with rephrased titles or citations of publications that the authors couldn’t verify by searching through databases and journal archives4.

    And although the scale of the problem remains uncertain, it’s clear that not only conferences are affected. An exclusive analysis conducted by Nature’s news team, in collaboration with Grounded AI, a company based in Stevenage, UK, suggests that at least tens of thousands of 2025 publications, including journal papers and books, as well as conference proceedings, probably contain invalid references generated by AI.

    Grounded AI is among the companies offering publishers tools for screening submissions for problematic references. Several publishers told Nature reporters that they have been exploring such tools or developing in-house versions.

    But some researchers are concerned that the problem will soon get out of hand. “We’re going to see a flood of fake references,” says Alison Johnston, a political scientist at Oregon State University in Corvallis.

    Another issue is deciding what to do about hallucinated citations that make it into the published literature. That’s a problem that academic publishers are wrestling with right now.
    Sources of error

    Citation errors are not new to academic publishing. “Even before generative AI, we already had so many inaccuracies in citations,” says Mohammad Hosseini, who studies research ethics and integrity at Northwestern University Feinberg School of Medicine in Chicago, Illinois. Issues have tended to include misspelling of authors’ names or errors in the year of publication, the title of the journal or the DOI. Another issue has been discrepancies between the information in the cited work and the details given by the paper citing it5,6.

    “Now the problem is not just inaccuracy, it’s about fake citations. It’s about fabricated citations, which is a whole different problem,” says Hosseini.

    Publishers told Nature that they are seeing increases in the number of fabricated and inaccurate citations in submissions, and they are taking steps to tackle the issue.

    Johnston, co-lead editor of the Review of International Political Economy (RIPE), a journal published by the UK-based Taylor & Francis, says that she rejected 25% of some 100 submissions in January “because of fake references”. She uses the plagiarism-detection software iThenticate to flag unusual or partial matches between the references in submitted papers and published bibliographies. Then she manually checks the suspicious citations. “I’m doing things now to try and detect hallucinated references that I wasn’t doing prior to 2025,” she says.

    Frontiers, based in Lausanne, Switzerland, has developed an in-house AI tool for flagging integrity issues at the point of submission, including references to irrelevant or retracted work and hallucinated citations. “Around 5% [of manuscripts] show potential reference-related issues flagged through our checks,” says Elena Vicario, Frontiers’ head of research integrity. But “not all flagged references ultimately turn out to be genuinely problematic”, she adds. That makes it challenging, Vicario says, to come up with a precise measure of the prevalence of any of these types of citation issue.

    Experiments using AI chatbots to generate papers have provided insights into how often LLMs produce citation errors and what types of error they tend to make. In one study, researchers prompted OpenAI’s GPT-4o LLM to generate six literature reviews on three mental-health disorders, and analysed the 176 references in those synthetic reviews7. Under these experimental conditions, they found that nearly 20% were fabricated references and could not be linked to actual research. And 45% of the remaining references, which corresponded to genuine publications, contained errors, often incorrect or invalid DOIs.

    In some cases, including in references in published articles, all of the component parts are made up, says Kathryn Weber-Boer, director of scientometrics at the London-based company Digital Science. (The firm is operated by the Holtzbrinck Publishing Group, which is the majority shareholder of Springer Nature, which publishes Nature. Nature’s news team is editorially independent of its publisher.) AI also hallucinates DOIs, both in references that are otherwise genuine as well as in fabricated ones, she adds.

    AI-generated references commonly combine fragments of genuine publications, say researchers who have studied the issue (see ‘How fakes can look real’). Joe Shockman, co-founder and chief executive of Grounded AI, calls such references ‘Frankenstein’ citations, likening their assembly to that of the fictional monster. “It looks real to a human being, but is not actually a reference to a real thing,” says Shockman, who is based in Ashland, Oregon.

    Although some types of error seem to implicate AI, others are less clear-cut, say researchers. “In today’s landscape, we have to recognize that there are human errors and there are machine errors, and those can often overlap,” says Weber-Boer.
    Published problems

    How many hallucinated citations are showing up in published research remains difficult to discern. To get an estimate, Nature’s news team joined forces with Grounded AI, which has developed an AI tool called Veracity that checks citations against scholarly databases and across the web, flagging ones that are invalid, irrelevant or cite retracted work.

    Nature and Grounded AI collaborated to analyse more than 4,000 publications from last year, covering five leading publishers: Elsevier, Sage, Springer Nature, Taylor & Francis and Wiley. Grounded AI randomly sampled these papers from Europe PMC — a repository of open-access biomedical research articles — and the bibliometric database Crossref, to include equal number of publications per month from each of the five publishers. The sample included published papers as well as book chapters and conference proceedings, and it cut across all subject areas in these publishers’ portfolios.

    Grounded AI’s tool looks for an exact match to a reference or the closest match it can find. It then flags citations with major issues, such as mismatched titles or DOIs, missing authors and incorrect journals, as well as more-minor issues. Citations that pointed to papers that couldn’t be found even though they should be easy to find — because the journal in question is indexed by scholarly databases, for example — were marked as especially problematic.

    After running the publications through the tool, Grounded AI assigned a risk score to each of the published papers, on the basis of the number of references that had major issues and how likely those issues were to have been generated by AI. Grounded AI determined that likelihood using data gleaned from a separate analysis that used two AI models to generate 20,000 synthetic papers; this allowed the company to identify the most common types of citation error that AI makes.

    Nature manually checked the 100 most suspicious publications and confirmed that 65 contained at least one invalid reference, meaning that it pointed to a publication that did not seem to exist (see ‘Finding the fabrications’). But 22 of the 100 most-suspicious papers had references that did point to genuine publications.

    For the remaining 13 papers, it was unclear whether all their citations pointed to existing research or not. These 13 papers included references to articles that were said to be published in regional journals in languages other than English, and references that had mismatches in metadata that looked like plausible human errors, for example.

    The analysis, which looked at reference lists from Crossref and full text from Europe PMC publications, turned up no clear trend across publishers. Each of the selected publishers had more than five publications with references that manual checks couldn’t validate.

    As a rough estimate, if the rate of 65 publications with at least one invalid reference out of some 4,000 publications analysed holds across the academic literature, it would suggest that more than 110,000 of the 7 million or so scholarly publications from 2025 contain invalid references.

    Nick Morley, Grounded AI’s co-founder and chief product officer, says that the types of citation problem seen in 2025 are different from those found by his team before the proliferation of LLMs. This fact, he says, points to the use of AI as a leading culprit.

    The true number of hallucinated references is almost certainly higher, says Weber-Boer, because the analysis focused on big publishers, which have more resources for checking citations systematically than do smaller publishers. Fields such as computer science, which has seen a surge in the use of LLMs to produce manuscripts8, might be more affected than other fields. What’s more, the Grounded AI analysis turned up a few hundred more publications that had some risk of hallucinated citations, suggesting that extra manual checking would have brought more such citations to light.

    Spokespeople for all five publishers said that they check references as part of their screening and editing process, and they intend to investigate the publications flagged by the Nature analysis. A spokesperson for Taylor & Francis said that some of the publications flagged were already under investigation by its ethics and integrity team.

    When it comes to hallucinated references, “there have been cases where authors have been able to clearly document where issues have occurred in the process of producing a manuscript, for example using a translation tool, and demonstrate that the rest of the paper can be relied upon, in which case the paper will be corrected”, says Chris Graf, Springer Nature’s research-integrity director. But, more often, these references reflect broader problems with the content, he says.

    Shockman says that the number of potentially problematic citations flagged by Veracity is an order of magnitude greater when it is used in pilot programmes to screen submissions on behalf of publishers than when it analyses publications. This suggests that publishers are catching a large proportion of such citations before they can make it into the literature.

    Nature’s collaboration with Grounded AI also highlighted, as many experts have noted, that the detection of invalid citations with automated tools is not error-free. One of the challenges is that journals have various ways of formatting references, and AI tools might fail to recognize references because of how they are styled. These types of problem showed up among citations that manual checks determined to be genuine despite having been flagged by Grounded AI.

    Another issue, says Weber-Boer, is that large-scale bibliometric databases might not index references that can’t be verified, meaning their metadata might not match what appears on the publishers’ websites. Some references do not contain their corresponding DOI, which makes it hard for automated tools to identify the cited paper, adds Weber-Boer. “We’re starting to get a handle on the characteristics of this problem, which are a precursor to understanding the scale of it,” she says.

    The Grounded AI team members acknowledge that not all the references their tool flags will be true positives, but they say they are continuing to improve its performance. IOP Publishing, based in Bristol, UK, is now using Grounded AI’s tool to screen submissions for problematic citations across all of its proprietary journals, says Kim Eggleton, head of peer review and research integrity. “We know it’s a problem, we just don’t know how big the problem is,” she says.
    Fake-citation fallout

    Other start-up firms that are designing AI tools to catch fake references are also finding that they cannot yet eliminate manual checks. One such firm is GPTZero, based in New York City, which is working with the International Conference on Learning Representations (ICLR) on a tool for screening submissions.

    GPTZero’s tool uses AI to search for the cited publications across the web as well as scholarly databases. Last year, the GPTZero team screened more than 700,000 citations in submissions to the ICLR 2026 and flagged 9,000 to be checked manually, says Alex Cui, the firm’s co-founder and chief technology officer. The flagged errors included titles that did not match those of any known publication, broken DOIs and citations attributed to authors with no connection to those works.

    ICLR 2026 programme chairs told Nature that around 1,000 manuscripts contained flagged citations. They rejected any that were found to contain hallucinated references, although they declined to say exactly how many.

    Other efforts and approaches are also emerging. Michał Wójcik, who has just completed a PhD in neuroscience at the Free University of Berlin, says that he uses tools based on the programming language Python to screen references he samples from Crossref, looking for mismatches in their metadata. So far, he has identified more than 500 papers with unresolved or mismatched DOIs, which he checked manually and reported on PubPeer — a platform for post-publication review.

    Another tool is CheckIfExist, an open-source platform that checks whether one or several references exist in scholarly databases. The tool, described in a preprint posted in January9, can help authors to avoid citing non-existent publications. Cabanac has worked with the French national research agency CNRS in Paris to develop another tool, called bibCheck, which has been made freely available to CNRS scientists. It checks whether a reference corresponds to an existing or retracted work.

    In Cabanac’s view, a paper with hallucinated citations should not be in the literature. It’s “like a plane flying with inexistent bolts”, he says. Once such a paper is identified, publishers must issue an expression of concern promptly and assess whether it needs to be corrected or retracted, he says.

    In several cases over the past year, publishers have retracted papers and books that were found to contain hallucinated citations.

    After Cabanac reported the International Dental Journal1 paper with the invalid reference to PubPeer in January, it was corrected in March to cite his preprint. Brett Duane, a public-dental-health researcher at Trinity College Dublin in Ireland and a co-author of the paper, which was about using ChatGPT to estimate carbon emissions in dental practices, says that ChatGPT was used to “help identify potentially relevant references for use in the manuscript, which were all independently reviewed and verified”. The reference to Cabanac’s work was “a corrupted citation, originating from an LLM suggestion” that was inadvertently added during drafting, he says, and did not affect the paper’s conclusions.

    Scholars are still debating whether and when hallucinated citations should be considered a form of research misconduct. Even major problems can happen unintentionally. For example, authors might use LLMs in a rush to format their reference list, unaware that AI has rephrased the citations, changed DOIs or added made-up references. Policies on AI use differ across journals. Most publishers require authors to disclose the use of AI, although what specific uses need to be disclosed varies. Policies also require human oversight of AI tools. Failing to verify their output could represent a lack of scientific rigour, according to several researchers who spoke to Nature.

    Even when the hallucinated citation doesn’t affect a paper’s findings and AI use is disclosed in accordance with journal policies, the journal must issue a public correction, Hosseini says.

    In a paper published in March, he and David Resnik, a bioethicist at the National Institute of Environmental Health Sciences in Research Triangle Park, North Carolina, suggest that citations that point to non-existent work in reviews and bibliometric studies should be classified as a form of research misconduct if the references serve as data that directly support findings and conclusions10. In this case, the invalid citations amount to data fabrication, they argue.

    In some cases, hallucinated citations might serve as a sign that the entire paper is fabricated, whether by an individual or a paper mill, a business that sells authorship slots. But the extent to which fabricated papers are contributing to the fake-citation problem is unclear.

    Spokespeople for Sage and Taylor & Francis told Nature that when a hallucinated citation is found in a submission, they might reject the manuscript or ask for a revision if the errors don’t affect the conclusions and don’t suggest wider misconduct. A spokesperson for Wiley said that “minor issues may be raised to the author for clarification”. Springer Nature said it withdraws submissions that are found to contain hallucinated references.

    Johnston says she is taking a hard line: when such a citation is found in a submission to RIPE, she says, the authors are prohibited from resubmitting the work to the journal.

    Hallucinated citations that make it into the academic literature can slow down and confuse other researchers’ efforts, and lead to false conclusions. Such errors can also create distrust in science, says Weber-Boer.

    Hosseini agrees: “Every fake citation is a problem in the literature that someone would have to deal with.”

    https://www.nature.com/articles/d41586-026-00969-z
    #AI #IA #intelligence_artificielle #citations #invention #recherche #littérature_scientifique #références #hallucination #LLM #bibliographie #Grounded_AI

  • Bibliographie pour celles et ceux qui s’intéressent au langage inclusif (34 pages de références bibliographiques !!)

    Liste non exhaustive d’articles scientifiques (revues à comité de lecture [peer-reviewed]) sur le lien entre #langage et #pensée, la représentation du #genre, le #genre_grammatical, le #langage_inclusif, et les #biais_de_genre (#androcentrisme,…). [Non-exhaustive list of scientific articles (peer-reviewed) on the link between language and thought, gender representation, grammatical gender, inclusive language, and gender biases (androcentrism,...)]

    https://osf.io/p648a/?view_only=a385a4820769497c93a9812d9ea34419
    #écriture_inclusive #bibliographie #ressources

    déjà signalé dans ce post ici :
    https://seenthis.net/messages/880539

  • Bibliothèques sonores de l’Association des Donneurs de Voix
    https://www.lesbibliothequessonores.org

    L’ADV-Bibliothèques sonores de France - plus de 100 bibliothèques et 3000 bénévoles - réalise et gère des enregistrements audio de livres et revues, prêtés gratuitement aux personnes empêchées de lire de façon permanente ou temporaire.


    https://www.radiofrance.fr/franceinter/podcasts/l-info-de-france-inter/l-info-de-france-inter-6198035

    #malvoyantes #aveugles #livres_sonores #Bibliothèques_sonores

    #donneurs_de_voix #don_de_voix #donner_de_la_voix

  • Bibliothèque de l’Université al-Isrāʾ
    https://www.visionscarto.net/bibliotheque-universite-al-isra

    READING IN #Gaza - RETOUR À LA TABLE DES MATIÈRES La Bibliothèque centrale de l’Université al-Isrāʾ [مكتبة جامعة الإسراء بغزة] sur le campus d’al-Zahrā, a été fondée en 2016 et détruite le 17 janvier 2024 par explosifs – 315 mines disposées– avec l’ensemble du campus. Avant sa destruction, le campus principal a été occupé pendant soixante-dix jours par l’armée israélienne. La destruction, spectaculaire, a été perçue comme un des paroxysmes de la quasi destruction totale à (…) Gaza

    / #Bibliothèques_universitaires

  • Reflexões do livro de Êxodo - Mergulhando na Palavra
    https://valdir.pagecord.com/reflexoes-do-livro-de-exodo-3e68db8a

    Na leitura de hoje quero destacar Arão e Moisés, os dois homens escolhidos por Deus e dois tipos distintos de servos e líderes.

     O texto mostra um Arão omisso, parece que medroso, com dificuldade de confrontar o povo de Israel no seu pecado, até certo ponto cúmplice no pecado do povo. Uma pessoa fraca.

     Moisés, ao contrário, ...

    #Bíblia #serviço

  • De #Google #Books à l’#IA : l’histoire numérique repasse les plats. – affordance.info
    https://affordance.framasoft.org/2026/02/de-google-books-a-lia-lhistoire-numerique-repasse-les-plats

    Contrairement à ce que pouvait écrire Céline, l’histoire, #numérique en tout cas, repasse parfois les plats. A fortiori lorsque ceux-ci ont un goût amer. Au début des années 2005, j’ai suivi, chroniqué et établi l’un de mes terrains de terrain de recherche sur la manière dont le projet #Google_Books allait (et aujourd’hui, avait) définitivement modifié et remodelé à son avantage non seulement l’entièreté des « métiers du livre » (#librairie, #édition, #bibliothèque), mais aussi initié et accompagné toutes les mutations ayant donné lieu à de nouveaux standards dans l’ensemble des #industries #culturelles. Vous trouverez trace de nombre de ces réflexions dans la rubrique éponyme de ce blog, ou bien dans cette version (qu’il faut que j’actualise) d’un cours que je donne sur le sujet à mes étudiantes et étudiants.

  • Kehrtwende nach Protest: Staatsbibliothek möchte Zettelkataloge vorerst erhalten
    https://www.tagesspiegel.de/berlin/kehrtwende-nach-protest-staatsbibliothek-mochte-zettelkataloge-vorerst-

    La bibliotèque principale de la capitale allemande conservera les fichiers élaborés pendant plusieurs siècles par ses bibliothéquaires.

    16.2.2026 - Nach der Diskussion um eine mögliche Entsorgung ihrer Zettelkataloge möchte die Staatsbibliothek das Archiv vorerst bewahren und so eine Erforschung ermöglichen. Die Institution hat nach eigenen Angaben eine Tagung organisiert, die überraschend großes Interesse an der Erforschung historischer Zettelkataloge gezeigt hat. Besonders großes Interesse gebe es an den Berliner Zettelkatalogen, die zu DDR-Zeiten entstanden seien, hieß es in einer Mitteilung.

    Worum geht es?

    Die Staatsbibliothek hatte im August 2025 mitgeteilt, dass die bis Ende 2026 im Außenmagazin Friedrichshagen gelagerten Zettelkataloge eingestampft werden sollten, um dringend benötigte Flächen für die Sanierung des Hauses am Potsdamer Platz freizumachen. Die Inhalte seien gesichert, ausgewählte Karten sollten als „Zeitkapseln“ erhalten bleiben.

    Die Entscheidung, die papierenen Originale des Zettelkatalogs einzustampfen, sei nicht leichtfertig getroffen worden, hieß es damals. Sie sei Ergebnis eines langwierigen internen Abwägungsprozesses, bei dem die verfügbaren Alternativen berücksichtigt worden seien. Das hatte teilweise für Kritik und Diskussionen gesorgt.

    Was sagt die Direktion?

    Nun folgt die Wende: „Das wissenschaftliche Symposium hat bisher kaum sichtbares, lebhaftes Interesse an der Erforschung historischer Zettelkataloge gezeigt“, wird Generaldirektor Achim Bonte in der Mitteilung der Staatsbibliothek zitiert. „Um für die gewünschten inhaltlichen und methodischen Erkenntnisprozesse hinreichend Zeit einzuräumen, sollen die bislang fehlenden Flächen innerhalb der Stiftung bis auf Weiteres gewährleistet werden können.“

    Marion Ackermann, Präsidentin der Stiftung Preußischer Kulturbesitz, erklärte: „Inwieweit sich die Gesellschaft Archivierungen und Musealisierungen leisten kann, ist immer auch ein gesellschaftlicher Aushandlungsprozess. Ich bin gespannt auf die demnächst zu erwartenden Beiträge und Forschungsfragen.“ (dpa)

    https://fr.wikipedia.org/wiki/Biblioth%C3%A8que_d%27%C3%89tat_de_Berlin

    La Bibliothèque d’État a été fondée en 1661 par Frédéric-Guillaume Ier de Brandebourg comme étant la « Bibliothèque du Prince-électeur » (Kurfürstliche Bibliothek) à Cölln an der Spree. En 1701, la bibliothèque a été rebaptisée « Bibliothèque royale de Berlin » et a conservé ce nom jusqu’à la fin de la monarchie en Allemagne en 1918, date à laquelle elle prit le nom de « Bibliothèque d’État prussienne ». .

    Le 10 mai 1933 les livres de la «Stabi» ont été épargné par les nazis quand ils ont brulé vingt mille livres volés dans les bibliothèques de la ville .

    Au cours de la Seconde Guerre mondiale l’ensemble des collections (à l’époque près de trois millions de livres et d’autres matériels) a été caché par sécurité dans trente monastères, des châteaux et des mines abandonnées. À la suite de cette guerre, environ 800 000 volumes et collections spéciales de la bibliothèque d’État de Berlin ont été détruits, perdus ou non retournés. Une partie de ces collections a été restituée et rassemblée à la fin des années 1970 dans un nouveau bâtiment conçu par Hans Scharoun dans le Kulturforum sur la Potsdamer Strasse à Berlin-Ouest et qui apparaît notamment dans le film Les Ailes du désir tourné à Berlin avant la réunification.

    En 1957, la Fondation culturelle prussienne est créée. Elle a pour mission de « transférer les biens culturels de Berlin pour des raisons liées à la guerre ». Toutefois la fondation, en raison de l’affrontement concernant le droit constitutionnel entre l’État fédéral et les Ländern, n’est intégrée à Berlin que quatre ans plus tard.

    En 1961, Berlin-Est et Berlin-Ouest célèbrent le tricentenaire de la Bibliothèque nationale (Bibliothèque de Berlin-Ouest à Marbourg et Bibliothèque d’État de Berlin-Est) dans un contexte politique de guerre froide.

    En 1963, le conseil d’administration a finalement lancé un appel d’offres pour la construction d’un nouveau bâtiment pour la bibliothèque d’État. En 1964, Hans Scharoun s’occupera de ce chantier.

    En 1978, après onze ans de travaux, la bibliothèque d’État du patrimoine culturel prussien est inaugurée, afin qu’il y ait une institution à la fois pour Berlin-Est et Berlin-Ouest.

    Après la réunification, le 1er janvier 1992, les deux bibliothèques sont rattachées sous le nom de Bibliothèque d’État de Berlin/Fondation culturelle prussienne, qui devient une propriété de la Fondation du patrimoine culturel prussien, qui se trouve désormais sur deux sites.

    #Allemagne #Berlin #bibliotjèque #archive #Stabi #histoire

    • Pagine nascoste

      All’origine del nuovo romanzo che la scrittrice #Francesca_Melandri sta preparando, «Sangue giusto», vi è l’urgenza personale di fare luce sulla generazione di suo padre, quei ’nativi fascisti’ la cui giovinezza si svolse interamente dopo la Marcia su Roma e che poi, dopo il 25 aprile 1945, della propria adesione al regime non parlarono più. Francesca sa che suo padre da giovane è stato fascista ma sa anche che Franco, sopravvissuto alla tragica campagna di Russia, ha poi subito come molti reduci una profonda conversione antifascista.

      Il ritrovamento negli archivi di un articolo che porta la sua firma rivela però alla figlia una realtà diversa.
 La scrittrice si avventura così in altre leggende, più collettive e pubbliche e non collegate alla biografia del padre, quelle legate alla guerra d’Abissinia (dove Franco non è mai stato), e la successiva occupazione così poco raccontata alla generazione post-bellica, tradizionalmente rappresentata come bonaria e praticamente indolore. La sua ricerca, condotta attraverso viaggi in Etiopia, ascolto di testimonianze e studio delle fonti storiche, racconta invece un’altra storia, fatta di stragi e violenze.

      Francesca studia e indaga per cinque anni, elaborando le sue conoscenze in una narrazione articolata, che intreccia il nostro passato coloniale con l’Italia razzista del nostro presente, riscoprendo i legami culturali dell’Italia contemporanea con quella mentalità intollerante mai realmente debellata alla radice e che oggi riemerge con prepotenza. Allo stesso tempo, molti dei testimoni che incontra, come Massimo Rendina (a lungo vicepresidente del’ANPI) che salvò suo padre dalle epurazioni sommarie di fine guerra mettendogli al collo il suo fazzoletto da partigiano, le rivelano come la realtà storica, quando s’incarna nelle persone, sia ben più interessante e viva sia dei silenzi che dei giudizi sommari.

      Il film è il racconto di questa ricerca, che intreccia passato e presente, rimozioni private e pubbliche, ambivalenze e contraddizioni, e del processo creativo che trasforma la realtà biografica e storica in quella restituzione della complessità che è la letteratura.

      https://filmitalia.org/it/film/100050
      #film #documentaire #film_documentaire

      –-
      ajouté à la métaliste sur le #colonialisme_italien :
      https://seenthis.net/messages/871953

  • Le site Anna’s Archive frappé par une suspension soudaine
    https://actualitte.com/article/128531/legislation/le-site-anna-s-archive-frappe-par-une-suspension-soudaine

    Anna’s Archive, bibliothèque en ligne non officielle spécialisée dans l’accès à des livres et textes numériques, a vu son nom de domaine principal, annas-archive.org, suspendu début janvier 2026. La plateforme reste toutefois accessible via d’autres adresses. Ses responsables affirment que cette suspension n’est pas liée à la récente mise en ligne d’une vaste archive musicale issue de Spotify.

    Publié le :

    06/01/2026 à 17:23
    Ewen Berton

    L’affaire intervient dans un contexte de pressions juridiques récurrentes visant ce type de bibliothèques parallèles, au croisement de la diffusion du savoir, des problématiques de droit d’auteur, et des usages numériques contemporains.

    Anna’s Archive a été lancé à l’automne 2022, quelques jours après la saisie de plusieurs noms de domaine du site Z-Library par le département américain de la Justice. L’objectif affiché était de garantir la continuité d’accès à des livres, articles et autres textes numériques, parfois difficiles à obtenir par les circuits traditionnels. Le site fonctionne comme une bibliothèque de l’ombre, mais aussi comme un moteur de recherche permettant d’explorer d’autres collections similaires.

    Contrairement à une bibliothèque classique, Anna’s Archive ne stocke pas nécessairement tous les contenus qu’il référence. Il s’appuie largement sur des copies existantes, hébergées ailleurs, et sur des systèmes de partage de fichiers appelés « torrent ». Cette architecture distribuée lui permet de rester accessible malgré les blocages ponctuels, tout en compliquant l’identification d’un point unique de contrôle.

    Au fil du temps, la plateforme a trouvé un public varié, allant de lecteurs à la recherche d’ouvrages introuvables à des chercheurs et développeurs. Ses bases de données ont notamment été utilisées pour l’entraînement de modèles d’intelligence artificielle, ce qui a contribué à accroître sa visibilité et, indirectement, l’attention des ayants droit.

    Une suspension de domaine inhabituelle

    Début janvier 2026, le domaine principal annas-archive.org est devenu inaccessible dans le monde entier. Son statut a été modifié en « serverHold », une mesure qui empêche un nom de domaine de fonctionner sur le système mondial d’adresses internet. Selon l’organisme de régulation ICANN, ce statut signifie que le domaine n’est plus activé et ne peut plus être résolu par les serveurs.

    Ce type de suspension est généralement décidé par le registre qui gère l’extension concernée. Dans le cas du « .org », il s’agit du Public Interest Registry (PIR), une organisation à but non lucratif américaine. Historiquement, le PIR s’est montré réticent à suspendre des domaines sans décision judiciaire explicite, y compris dans des affaires très médiatisées.

    Interrogé par plusieurs médias spécialisés, le PIR s’est refusé à tout commentaire sur les raisons de cette décision. Le bureau d’enregistrement du site, la société Tucows, a indiqué de son côté que seule l’autorité du registre pouvait imposer un tel statut, et qu’elle n’avait reçu aucune information préalable à ce sujet.

    Face aux interrogations, l’équipe d’Anna’s Archive a réagi publiquement via un message publié sur Reddit.
    Capture d’écran traduite du message d’Anna’s Archives sur Reddit
    Capture d’écran traduite du message d’Anna’s Archive sur Reddit.

    Dans ce message, les responsables insistent sur le caractère récurrent de ce type de mesures à l’encontre des bibliothèques parallèles. Ils soulignent également que le site reste accessible par d’autres extensions, et renvoient les utilisateurs vers des sources publiques pour obtenir les adresses à jour. La communication se conclut par un appel aux dons, présenté comme nécessaire pour maintenir l’infrastructure.

    Cette prise de parole vise aussi à dissiper un soupçon apparu récemment. Deux semaines avant la suspension, Anna’s Archive avait annoncé la constitution d’une archive de près de 300 téraoctets de musique issue de Spotify, une initiative très médiatisée qui a pu laisser penser à un lien direct avec la mesure prise contre le domaine.

    Un contexte juridique déjà chargé

    La suspension du domaine intervient alors qu’Anna’s Archive fait face à plusieurs contentieux. Le plus notable est une action en justice intentée par l’OCLC, une organisation qui gère le catalogue mondial WorldCat pour le compte de bibliothèques. L’OCLC accuse le site d’avoir collecté illégalement des données issues de son catalogue, représentant plusieurs téraoctets d’informations.

    Dans une procédure déposée en novembre, l’OCLC a demandé une injonction permanente visant à empêcher toute nouvelle collecte ou diffusion de ces données, ainsi que la suppression des copies existantes. L’organisation espère qu’une telle décision pourrait inciter des intermédiaires techniques, comme les hébergeurs ou les registres de noms de domaine, à agir. À ce stade, le tribunal ne s’est pas encore prononcé.

    Par ailleurs, Anna’s Archive a déjà été bloqué dans plusieurs pays et a perdu par le passé d’autres noms de domaine. Ces précédents expliquent en partie la stratégie du site, qui multiplie les adresses alternatives afin de rester accessible malgré les pressions.
    Entre accès au savoir et conflits de droits

    Au-delà de l’aspect technique, l’affaire illustre les tensions persistantes autour de la diffusion des œuvres écrites à l’ère numérique. Pour ses défenseurs, Anna’s Archive répond à un besoin d’accès à la connaissance, notamment pour des lecteurs éloignés des réseaux institutionnels. Pour les ayants droit et certaines institutions, il s’agit avant tout d’une mise à disposition non autorisée d’œuvres protégées.

    La suspension du domaine annas-archive.org ne signe donc pas la disparition du site, mais marque une nouvelle étape dans un affrontement ancien. Elle pose aussi la question du rôle des acteurs intermédiaires d’internet, comme les registres de noms de domaine, dans l’équilibre entre respect du droit et circulation des textes.

    Crédits photo : Kevin Ku Pexels

    Par Ewen Berton
    Contact : eb@actualitte.com

    #Bibliothèque#Censure #DNS #.org #Infrastructure